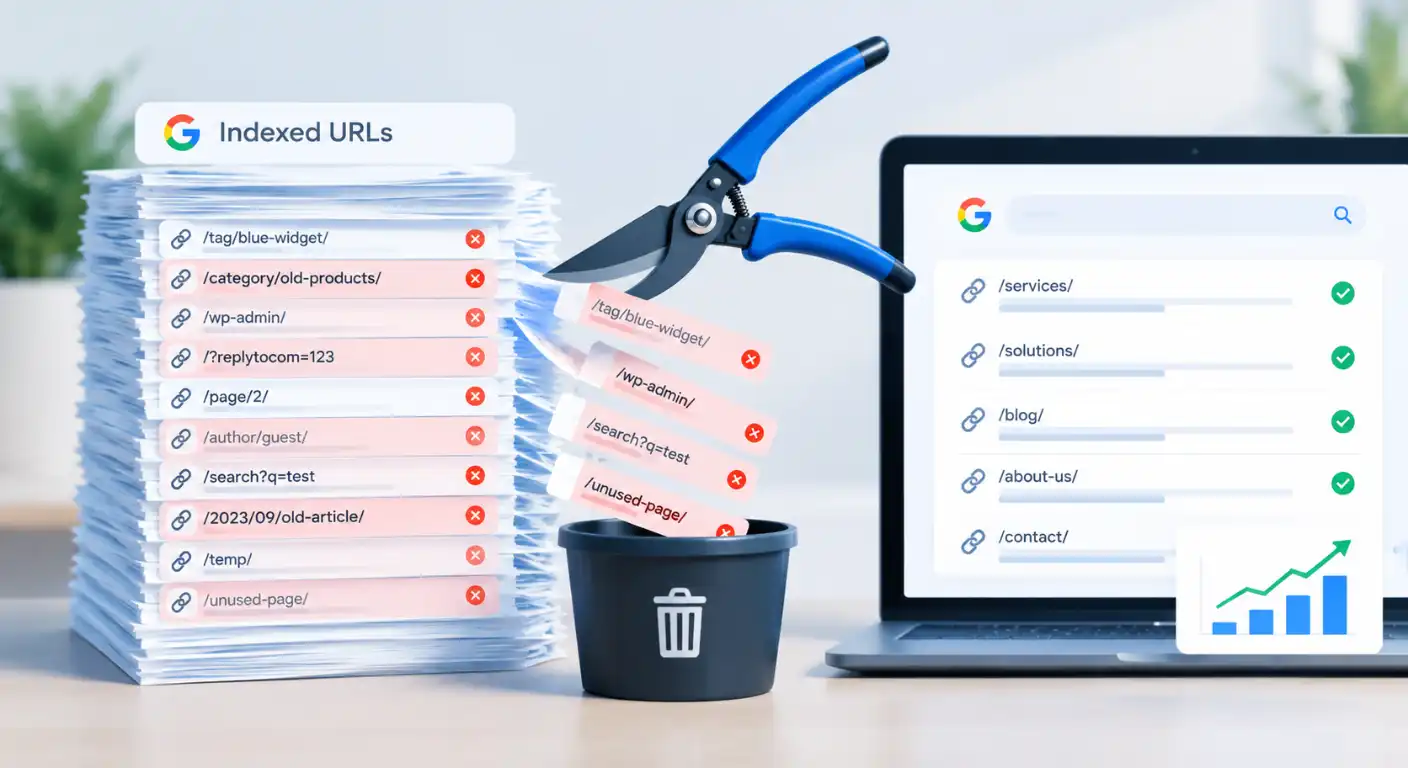
You publish 200 high-quality products or blog posts, but when you run a site:yourdomain.com search or inspect Google Search Console, you discover 15,000 indexed URLs. Hundreds of auto-generated parameter links, empty search results, faceted filters, and staging leaks are quietly sitting in search engine databases.
This hidden technical flaw is Index Bloat.
For enterprise sites, e-commerce stores, and large dynamic web applications, index bloat is a silent organic traffic killer. It quietly drains your domain equity, exhausts your site’s finite crawl budget, and dilutes overall sitewide quality scores: causing your primary, revenue-generating pages to drop in rankings or sit un-indexed in Search Console.
What We Will Cover in This Article
In this blog, we will step away from basic theory and execute an actionable, step-by-step index pruning framework:
The Business Impact: Why index bloat actively damages sitewide domain equity and wastes search engine crawl resources.
Identification Playbook: Precise methods to uncover bloat using Google Search Console, advanced site search operators, and technical crawlers.
The Root Causes: Identifying dynamic parameters, faceted navigation, staging leaks, and tag archives.
Strategic Pruning Framework: Step-by-step cleanup workflows utilizing
noindex, 410 Gone status codes, canonical consolidation, and URL removal tools.Prevention Rules: Architectural guardrails to keep your index clean permanently.
What Is Index Bloat and Why Does It Drain Domain Equity?
Index Bloat occurs when search engines discover, render, and retain a massive volume of low-value, duplicate, auto-generated, or obsolete URLs in their search database.
Instead of your index footprint reflecting only your highest-performing, revenue-generating pages, the search engine’s index becomes cluttered with thousands or even millions of “junk” URLs (such as faceted navigation filters, internal search results, tagged archives, or staging leaks).
INDEX BLOAT EFFECT | |
Ideal Index Footprint | Core Pages (100% High Value) |
Bloated Index Footprint | Core Pages (10%) + Low-Value URLs (90%) |
Quality Score Dilution: How Low-Value URLs Drag Down Your Site’s Authority
Search engines do not evaluate web pages in complete isolation; they assess domain health through aggregated, sitewide quality signals. When an indexer stores thousands of low-value, thin, or near-duplicate URLs alongside your core assets, it severely dilutes your domain’s overall quality ratio.
How Dilution Impacts Sitewide Authority:
Information Gain Depletion: Storing vast amounts of redundant content lowers the average information gain score across your entire domain.
Diluted Link Equity (PageRank): Internal link equity that should consolidate into primary categories or core product pages gets fragmented across parameter variations, thin tag pages, and paginated paths.
Algorithmic Quality Penalties: Search algorithms evaluate the proportion of high-quality vs. low-quality pages on a site. A bloated index signals to search engines that the majority of your domain’s content provides minimal user value, suppressing the ranking potential of your legitimate pages.
Crawl Budget Exhaustion: How Junk Pages Delay Priority Content Crawling
Search engines allocate finite resources: computational power, energy, and storage space to every domain. This resource allocation is managed via two distinct mechanisms: Crawl Budget and Indexing Capacity.
Crawl Budget Exhaustion: When search bots (like Googlebot) spend their scheduled fetch requests crawling infinite filter combinations, session IDs, or internal search result pages, they run out of crawl budget before reaching your newly published or updated high-value URLs.
Rendering & Storage Threshold Limits: Executing JavaScript for dynamic, bloated pages consumes significant Web Rendering Service (WRS) processing queue time. Over time, search engines raise the inclusion threshold for your site, causing valuable pages to sit in states like “Discovered – Currently Not Indexed” or “Crawled – Currently Not Indexed”.
Where Do Junk Pages Come From? The 3 Primary Root Causes of Bloat
Index bloat rarely happens by accident; it is almost always the result of automated site architecture, CMS default behaviors, or technical oversight during server deployment.
To clean up a bloated index permanently, you must first identify the structural sources generating unwanted URLs.
E-Commerce Faceted Filters: How Parameter Strings Cause URL Explosion
Faceted navigation allows users to filter products by color, size, brand, price, and rating. While essential for user experience, it is the single largest contributor to enterprise index bloat.
The Mechanism:
When filter parameters are appended to the URL query string without proper crawl controls or JavaScript handling, search bots treat every single parameter combination as a unique, standalone URL.
If your catalog has 50 categories and 10 filter options, a single category can generate thousands of duplicate or near-duplicate URLs that offer zero unique search value.
Internal Site Search, Tag Archives, and Single-Item Author Pages
Many content management systems (CMS) automatically create public, crawlable archive pages by default.
Internal Search Result Pages (
/search?q=...): If your site’s internal search bar generates static, indexable URLs and lacksnoindexdirectives, malicious actors or automated web scrapers can use your search field to generate thousands of spammy, auto-generated pages on your domain.Tag Archives (
/tag/topic): Creating multiple tags for a single blog post (e.g., tagging an article with “SEO”, “Technical SEO”, “SEO Tips”, and “SEO Guide”) generates four separate archive pages that contain identical content snippets.Thin Author Archives (
/author/admin): Single-author blogs or sites where guest authors write a single post often generate empty or single-item author pages, adding thin, low-value documents to search engine databases.
Server Leaks: Unprotected Staging Subdomains and Duplicate HTTP/HTTPS Paths
INFRASTRUCTURE DUPLICATION SOURCES | |
Staging Leaks: | staging.yourdomain.com / dev.yourdomain.com |
Protocol Mixes: | http://yourdomain.com vs. https://yourdomain.com |
Hostname Variances: | yourdomain.com vs. www.yourdomain.com |
Infrastructure and server misconfigurations can inadvertently leak entire duplicate versions of your website directly to search crawlers.
Why Server Leaks Happen:
Unprotected Staging Sites: Developers often deploy staging subdomains (
staging.site.comordev.site.com) without password protection or IP restrictions. If an internal link leaks or a crawler finds the subdomain, Google will crawl and index the entire staging environment as duplicate content.Missing HTTP to HTTPS / Non-WWW Redirects: If your server responds with a
200 OKHTTP status code on bothhttp://andhttps://(or bothwwwand non-www) without enforcing strict301permanent redirects, search engine indexers may index two identical versions of your entire domain.
How to Audit and Identify Index Bloat Across Your Domain
Identifying index bloat requires cross-referencing multiple data sources. Relying on a single reporting tool often leads to false positives or missed parameter leaks.
A structured diagnosis compares what search engines have stored against what you actually intended to publish.
site: Search Operators vs. XML Sitemaps: Spotting Discrepancies Fast
The fastest initial indicator of index bloat is comparing your submitted XML sitemap count against Google’s estimated indexed URL count.
Step 1: Run the site: Search Operator Baseline
Search site:yourdomain.com in Google. The total result count displayed at the top provides a rough estimate of Google’s indexed URL footprint for your domain.
Step 2: Isolate Specific Parameter Patterns
To locate exact sources of bloat using Google search operators, execute targeted queries:
Faceted Navigation/Parameters:
site:yourdomain.com inurl:?orsite:yourdomain.com inurl:sort=Internal Search Leaks:
site:yourdomain.com inurl:/searchorsite:yourdomain.com inurl:?s=Staging/Subdomain Leaks:
site:yourdomain.com -inurl:wwworsite:staging.yourdomain.com
Step 3: Compare Against Valid XML Sitemaps
Your XML sitemap should contain only 200 OK, canonical, indexable URLs. If your sitemap lists 2,000 URLs but Google reports 25,000 indexed pages, 90%+ of your index footprint consists of unmanaged index bloat.
Merging GSC & GA4 Data: Finding Zero-Traffic Indexed Pages
To confirm whether indexed URLs are actively harming your domain or simply sitting dormant, perform a data merge between Google Search Console (GSC) and your analytics platform (e.g., Google Analytics 4).
The Audit Workflow:
Export All Indexed URLs from GSC: Navigate to GSC → Indexing → Pages → “Indexed”. Export the full URL list.
Export Organic Landing Pages from Analytics: Pull a list of all URLs that received at least 1 organic landing page session over the last 90–180 days.
Isolate Zero-Traffic Indexed URLs: Run a VLOOKUP / Merge between both lists.
Evaluate Findings: Any URL pattern that is indexed in GSC but generates 0 organic impressions and 0 clicks over 6 months is a prime candidate for index pruning.
Screaming Frog Parameter Mapping: Bulk Crawling Dynamic URL Patterns
While Google Search Console provides sampled data, site crawlers (like Screaming Frog SEO Spider) allow you to map every parameter string, non-canonical URL, and orphan path across your entire architecture.
The Bulk Detection Workflow:
Group by Parameter Keys: In Screaming Frog, navigate to the URL Parameters tab. This aggregates all query strings (e.g.,
?sort=,?color=,?sessionid=) and shows the total volume of secondary URLs generated per parameter.Identify Canonicalized Bloat: Filter for Indexability → Non-Indexable with a status of Canonicalised. If your site generates 50,000 canonicalized filter variations that are still internally linked and fetched, search bots are spending massive crawl budget processing non-canonical bloat.
Locate Orphan Parameter Pages: Connect your GSC and GA4 APIs directly into Screaming Frog under Configuration → API Access. Crawl the site and filter by “Orphan Pages” (URLs found in GSC/Analytics but not present in your internal HTML link structure).
Decoding GSC Page Indexing Statuses: Separating Contamination from Normal Duplication
GSC INDEXING STATUS DIAGNOSIS | |
GSC Status Description | Index Bloat Severity Level |
“Indexed” (with parameters/filters) | CRITICAL BLOAT (In SERPs) |
“Alternate page with proper canonical” | CRAWL BUDGET WASTE (Ignored) |
“Duplicate without user canonical” | RISK OF UNPREDICTABLE INDEXING |
“Excluded by ‘noindex’ tag” | CONTROLLED (Processing ok) |
Inside GSC’s Page Indexing Report, not all reported URLs are problematic. You must distinguish between handled bloat and active index contamination.
Diagnostic Framework:
“Indexed” Pages (The Primary Danger): Filter your Indexed list for parameter strings (
?) or path patterns like/search,/tag/, or/page/. Any low-value URL sitting in this bucket actively dilutes domain quality and needs immediate pruning.“Alternate page with proper canonical tag”: These URLs are not sitting in Google’s index, but Googlebot is actively crawling them to confirm the canonical signal. High volume here points to a Crawl Budget issue, not an indexation quality issue.
“Duplicate without user-selected canonical”: Google detected duplicate/bloat pages, but you failed to provide explicit
rel="canonical"ornoindexdirectives. Google is making an algorithmic choice on which URL to index, creating ranking volatility.
How to Safely Remove Unwanted URLs Without Losing Organic Traffic
Removing thousands of bloated URLs without accidentally destroying legitimate search traffic requires a structured execution framework. Executing the wrong response code or directive on the wrong page type can result in severe traffic drops or permanent loss of link equity.
noindex vs. 410 Gone vs. 301 Redirects: Selecting the Right Removal Directive
Choosing the correct removal mechanism depends entirely on whether the target URL possesses relevance, external link equity, or ongoing operational utility.
1. 301 Permanent Redirect (Consolidation)
When to Use: Outdated product pages, merged category paths, or duplicate URLs that have external backlinks, historic organic traffic, or high PageRank.
Mechanism: Passes ~95–99% of link equity to the new primary target while instructing search engines to transfer indexation signals.
Execution Rule: Redirect the bloat URL strictly to the most relevant equivalent page (e.g., an out-of-stock product to its direct parent category), never mass-redirect thousands of unrelated parameter URLs to the homepage, as Google will treat them as Soft 404s.
2. noindex Directive (Removal with UX Preservation)
When to Use: Pages that must remain accessible to humans for operational or navigation reasons, but hold zero value in search engine databases (e.g., internal search results, account dashboards, checkout flows, or paginated archives).
Mechanism: Keeps the page accessible via
200 OK, but instructs indexers to purge the document during parsing.Execution Rule: Ensure the page remains allowed in
robots.txtso crawlers can fetch the response and parse thenoindexheader.
3. 410 Gone HTTP Status Code (Hard Pruning)
When to Use: Completely dead, spammy, auto-generated, or hacked URLs that possess zero link equity, zero traffic, and zero user value.
Why
410beats404: While a404 Not Foundtells bots a page is missing (causing Googlebot to re-crawl it repeatedly for weeks to verify), a410 Gonesignals explicit, intentional, and permanent deletion. Search engines drop410responses from their index significantly faster than standard404pages.
Safe Parameter Pruning: Cleaning E-Commerce Filters Without Organic Rank Drops
Pruning parameter bloat across large-scale e-commerce stores carries a risk: if a dynamic parameter URL currently drives organic long-tail traffic, stripping it without analysis can cause an immediate revenue drop.
Step-by-Step Safe Clean-up Process:
Perform a Revenue & Traffic Guardrail Check: Before modifying parameter handling, check Google Search Console for any parameter string (e.g.,
?color=black) generating impressions or clicks. If a parameter URL drives traffic, do not prune it—either optimize it into a clean static category URL or consolidate it viarel="canonical".Implement Canonical Consolidation First: For faceted navigation variations that contain identical products, set the
<link rel="canonical">on all parameter variations pointing back to the core, clean base URL (e.g.,/shoes/?color=red→/shoes/).Clean Internal Linking Patterns: Ensure your site’s faceted navigation uses JavaScript-driven state changes or clean AJAX fetching instead of rendering standard HTML
<a href="?filter=...">links. If crawlers cannot discover raw parameter links in the DOM, they will not generate bloat.Deploy Google Search Console Temporary Removals for Urgent Leaks: If a staging environment or major parameter leak exposes 100,000+ junk pages in SERPs instantly, use the GSC URL Removal Tool (Indexing → Removals) to temporarily hide the directory pattern while server-side
410ornoindexrules deploy.
How to Prevent Future Index Bloat?
Cleaning up a bloated index without changing site architecture only creates temporary relief. As soon as new product lines, tags, or dynamic filters launch, search engines will discover and index those new variations.
Long-term index hygiene requires enforcing permanent architectural guardrails at the development level.
Replacing Dynamic Filter URLs with Client-Side AJAX and JavaScript State Changes
The most effective way to eliminate parameter bloat is to prevent search engines from discovering dynamic filter URLs in the raw HTML response.
1. Transition to Client-Side AJAX / History API Navigation
Replace
<a>Links on Filters: Do not wrap filter options (colors, sizes, sorting) inside standard HTML<a href="...">tags. When search bots crawl the DOM, they parse everyhrefattribute and add it to the crawl queue.Use Event Listeners & State Changes: Implement filtering via JavaScript
addEventListenerusing<button>elements or custom UI components. Fetch filtered product sets via API endpoints (AJAX) and update the browser view dynamically without altering the underlying crawlable URL structure.
2. Strict Parameter Disallow Rules in robots.txt
Once you consolidate filter canonicals, block crawler access to non-essential query strings inside robots.txt to preserve crawl budget:
User-agent: *
# Block dynamic sorting and pagination filters
Disallow: /*?sort=
Disallow: /*?dir=
Disallow: /*&sort=
Disallow: /*?price=
Disallow: /*?sessionid=
Critical Caveat: Only apply
robots.txtblocks to parameter strings after existing index bloat has been purged vianoindexor410status codes. Blocking a parameter URL inrobots.txtwhile it is already indexed prevents crawlers from fetching the page to see removal directives, leaving the bloat trapped in search results.
Dynamic XML Sitemap Hygiene: Automatically Stripping Dead and noindex URLs
Your XML sitemap serves as the primary indexation blueprint for search engines. It must function as an absolute list of clean, canonical, and indexable URLs.
Automated Validation Rules for CI/CD Pipelines:
Zero Non-200 URLs: Programmatically validate that redirect chains (
301/302), dead pages (404/410), or server errors (500) are automatically stripped from the XML feed during generation.No
noindexor Canonicalized URLs: Cross-reference sitemap entries against meta robots tags and canonical targets. An XML sitemap that submits anoindexpage creates direct signal confusion in Google Search Console.Dynamic Indexing Thresholds: For large-scale publishing or e-commerce sites, split XML sitemaps by category, product type, or publication date (e.g.,
sitemap-products-2026.xml). This makes tracking indexation rates across specific site modules significantly easier inside Google Search Console.
Frequently Asked Questions About Index Bloat
Will fixing index bloat immediately restore dropped organic traffic?
Index pruning improves site quality scores and crawl efficiency gradually, not overnight. Google needs to re-crawl the site, process 410/noindex directives across historical queues, and recalculate sitewide domain quality scores over several crawl cycles (typically 2 to 8 weeks depending on domain crawl frequency).
Can I just block bloated parameter URLs in robots.txt to remove them from Google?
No. Blocking a URL via robots.txt only prevents Googlebot from fetching the page body. It does not remove an already-indexed URL from search results. If Googlebot is blocked, it cannot read a noindex tag or 410 status code. To remove indexed bloat, the page must remain crawlable until Google parses the removal directive.
Does the Google Search Console “Removals Tool” permanently fix index bloat?
No. The GSC Removals tool is a temporary emergency mask that hides URLs from search results for roughly 6 months. It does not stop Googlebot from indexing or storing those URLs in the back-end. You must deploy permanent server-side controls (410 Gone, noindex, or canonical consolidation) while the temporary removal is active.
How do I prune low-quality pages without accidentally deleting URLs that drive long-tail traffic?
Always run a 3-point data cross-reference before pruning: export all indexed URLs from GSC, join them with GA4 90-day organic landing page sessions, and verify backlink profiles. Any URL with historic revenue, clicks, or external links should be canonicalized or consolidated via 301 redirects rather than flat 410 deletion.
Conclusion
Index bloat is a silent organic traffic killer that dilutes your site’s quality ratio, drains finite crawl budget, and traps priority pages in un-indexed queues. Resolving complex parameter proliferation, staging leaks, and directive conflicts requires a precise execution plan. Choosing the wrong status code or blocking directives prematurely can instantly drop legitimate rankings. By systematically auditing your search footprint, applying targeted noindex and 410 directives, and enforcing server-side architectural guardrails, you ensure search engines evaluate and index only your highest-value assets.
Reclaim Your Domain Equity
Every un-indexed parameter or duplicate tag page quietly dilutes your domain’s overall quality score. If you’re managing a large e-commerce store or enterprise site and suspect index bloat is holding back your primary keywords, I can help you prune it safely.
Explore my eCommerce SEO Services | Enterprise SEO Services | Technical SEO Services OR Contact to Audit Your Site’s Indexation Health →
Explore Other Articles Under Technical SEO Side
Pillar Blogs
What is Technical SEO? (Parent Blog)
- Crawlability and Indexability in SEO (Child Blog)