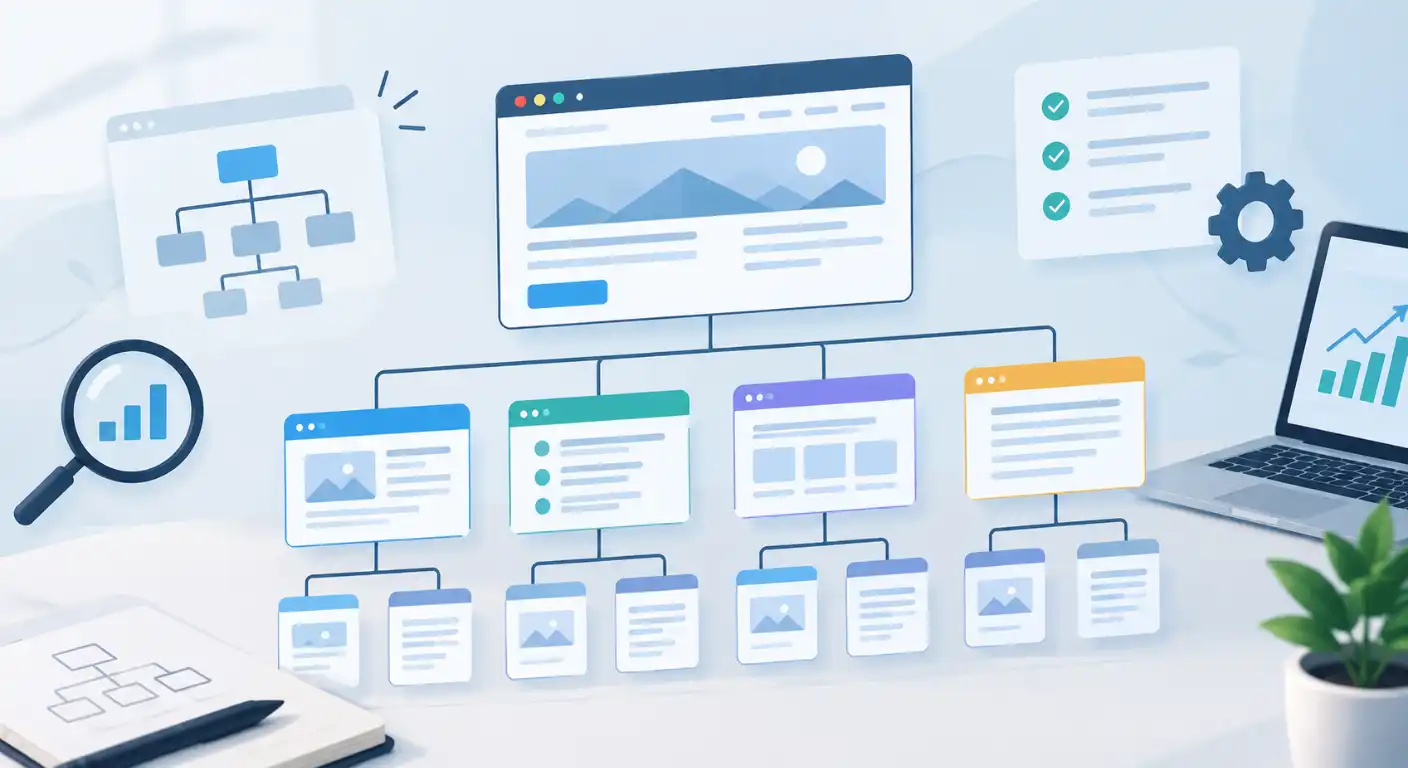
In website architecture, URLs are far more than static web addresses or database endpoints. They represent the foundational blueprint of your website’s Information Architecture (IA). Yet, during platform redesigns, CMS migrations, or catalog expansions, URL design is frequently relegated to an aesthetic afterthought, relying on default platform slugs or messy dynamic parameters.
This architectural oversight introduces severe technical debt. Unstructured URL paths create exponential crawl bloat, confuse search engine rendering engines, erode user click-through rates (CTR), and split internal authority across duplicate paths. When search crawlers encounter ambiguous, deep, or non-deterministic URL structures, their ability to efficiently parse site taxonomy and evaluate topical relevance degrades rapidly.
To build a resilient organic search framework, technical teams must treat URLs as permanent semantic assets. Designing SEO-friendly URL structures requires balancing human readability, crawler accessibility, and engineering scalability.
In this comprehensive guide, we will break down:
- The strategic mechanics of URL architecture and crawl budget optimization.
- The exact anatomy of high-performing URLs (slug formatting, lowercase enforcement, and folder depth).
- Technical protocols for managing dynamic parameters, dynamic routing, and crawler traps.
- Scalable URL taxonomies for e-commerce and large-scale enterprise environments.
- The risk management framework for executing URL changes and redirects without sacrificing domain authority.
The Strategic Impact of URL Architecture
URLs as Primary Semantic & Contextual Signals
Before search engine crawlers issue an HTTP request to fetch a page’s full HTML DOM, the URL string itself provides the very first contextual signal about the page’s contents. Modern search bots including automated web crawlers and AI answer engine parsers, evaluate URL patterns to construct an initial topical graph of your site.
A clean, structured path like /technical-seo/site-architecture/url-structure/ communicates clear hierarchical relationships:
The root domain hosts the primary authority.
The top-level directory (
/technical-seo/) establishes the broad topical entity.The subfolder (
/site-architecture/) defines the structural context.The leaf slug (
/url-structure/) specifies the targeted subject matter.
When search crawlers encounter this predictable pattern, they can instantly map topical relationships across your site’s nodes. Conversely, non-descriptive URL strings containing random database keys (/page.php?id=89432&type=cat) force search engines to rely entirely on post-render DOM parsing to determine context, increasing processing overhead and delaying indexation.
The User Trust, Shareability, and CTR Correlation
URL architecture plays a direct role in user psychology and organic Click-Through Rate (CTR). In search engine result pages (SERPs), modern engines display breadcrumb-style snippet paths above the main title tag. A clean, human-readable URL reinforces search intent and signals security and relevance before the user even clicks.
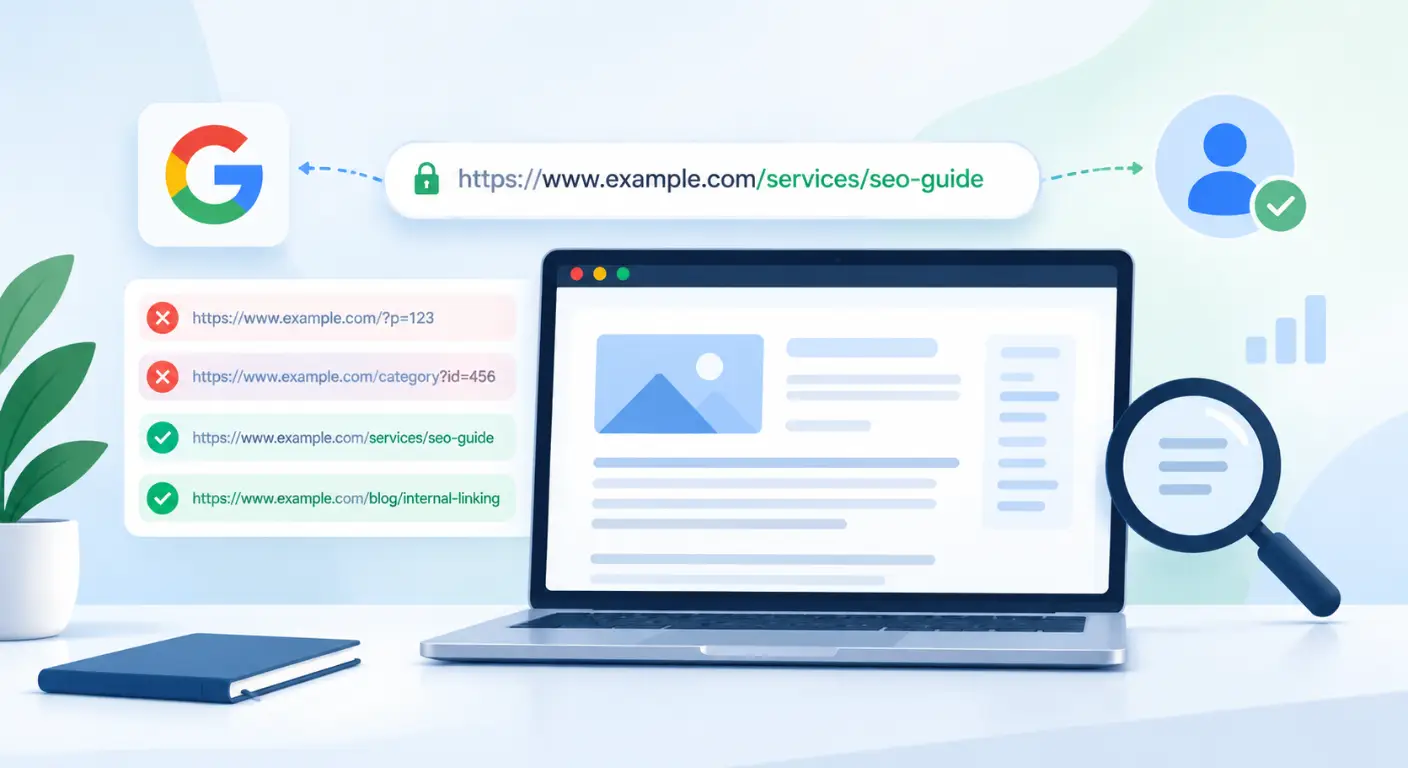
Consider how users process two competing search results:
Unoptimized:
https://example.com/products/v2/index.jsp?cat=12&item=99182Optimized:
https://example.com/shoes/mens/running-shoes
The second example clearly communicates what the user will encounter upon landing. Furthermore, clean URLs improve social shareability and backlink acquisition. When third-party websites paste raw URLs as anchor text, descriptive slugs naturally pass rich, keyword-relevant anchor signals back to your domain, reinforcing contextual authority.
Crawl Budget & Indexation Efficiency
Search engine crawlers allocate a finite Crawl Budget to every domain, governed by the site’s authority and server responsiveness. Crawl efficiency is the measure of how effectively Googlebot spends that budget fetching valuable, indexable content rather than wasting requests on redundant or non-canonical paths.
Unstructured URL architectures are the leading cause of crawl budget exhaustion. Poorly designed routing can generate infinite URL variations through:
Case sensitivity mismatches (
/Pagevs/page).Unnecessary folder depth trailing slashes.
Uncontrolled tracking, sorting, and session parameters.
When crawlers spend 60–80% of their request allowance navigating redundant or infinite URL paths, high-priority landing pages, new product releases, and updated content remain uncrawled in the queue. Establishing a clean, predictable URL architecture acts as a primary firewall against crawl waste, ensuring search engines discover and index critical assets efficiently.
Anatomy of a High-Performing URL
While Google’s crawlers can navigate complex directory trees, excessively deep folder paths (/shop/v1/apparel/footwear/mens/running/product-123) introduce friction:
Crawl Efficiency: Deeply nested subfolders can obscure the primary topic and dilute keyword signals within the URL string.
Click Depth Alignment: Search engines assign higher internal authority to pages reachable within 1 to 3 clicks from the root domain.
Best Practice: Maintain a logical subfolder depth that accurately reflects your site’s hierarchy without creating unnecessarily deep folder chains. If a subfolder does not represent an indexable category hub, flatten the URL path (e.g., preference /running-shoes over /catalog/item/v2/running-shoes).
Slug Optimization Best Practices
The slug represents the final segment of the URL path and directly communicates the page’s core subject matter. Adhering to strict technical formatting rules prevents indexation bugs and ensures consistent indexing.
1. Hyphens (-) vs. Underscores (_)
Search engine parsers treat word separators in URLs strictly based on syntax standards:
Hyphens (
-): Interpreted as explicit word spaces. A slug formatted as/technical-seo-guideis parsed as three distinct words:technical,seo, andguide.Underscores (
_): Treated as word joiners. A slug formatted as/technical_seo_guideis parsed as a single concatenated token:technical_seo_guide.
Rule: Always use hyphens as word separators across all URL slugs.
2. Strict Lowercase Enforcement
URL specifications (RFC 3986) state that path segments are case-sensitive on Linux-based web servers. Consequently, the following two URLs are technically distinct web resources:
https://example.com/Technical-SEO/https://example.com/technical-seo/
If a server serves identical content on both paths, search crawlers treat them as duplicate URLs, splitting incoming backlink signals and internal equity.
Rule: Enforce strict lowercase routing at the server or application level. Automatically issue 301 redirects from uppercase variants to lowercase canonical paths.
3. Stripping Stop Words & Superfluous Clutter
Unnecessary stop words (a, an, the, of, and, in) add length to the URL string without adding search intent value. Trimming these words creates cleaner, more readable slugs:
| Unoptimized Slug | Optimized Slug |
/the-role-of-technical-seo-in-modern-growth | /technical-seo-growth-rule/ |
/best-shoes-for-running-in-the-rain | /raining-running-shoes/ |
/product-item-id-88912-blue-shirt | /blue-shirt |
4. Eliminating Dynamic Dates and Versioning
Including publication dates (/2026/10/url-structure/) or platform version strings (/v2/seo-guide) in URL paths creates long-term architectural debt:
When evergreen content is updated, the date in the URL makes the resource appear outdated to users in search snippets.
Changing the URL later to remove the date forces unnecessary 301 redirects.
Rule: Keep slugs evergreen and focused purely on core topical entities.
Parameter URLs, Dynamic Routing, and Crawler Traps
When building scalable websites particularly large e-commerce catalogs, programmatic databases, or multi-faceted directories, managing dynamic query strings is one of the most critical challenges in technical SEO. Uncontrolled parameter routing can instantly exhaust your crawl budget, split internal link equity, and trigger severe index bloat.
Why Parameters Occur and Their SEO Risk
Query parameters are added to URLs to pass dynamic state information to the server. Common use cases include:
Sorting & Filtering: Ordering products by price (
?sort=price_asc) or narrowing inventory by attribute (?color=red).Session Tracking & Marketing Analytics: Appending campaign tags (
?utm_source=google&utm_medium=cpc) or session IDs (?sessionid=99281).Pagination & Internal Search: Splitting long lists across pages (
?p=2) or displaying internal search queries (?q=running+shoes).
While necessary for user functionality, these parameters create duplicate content risks. If a single product or category can be accessed via dozens of parameter combinations, search engines treat each unique string as a separate URL, splitting incoming link equity and diluting topical signals.
Parameter URLs & Dynamic Routing
At the heart of parameter-driven architecture is the distinction between static directory paths and dynamic query strings. When search crawlers encounter parameter URLs, they evaluate how the server handles variable data layers.
The Mechanics of Parameter Bloat
Combinatorial multiplication occurs when multiple independent parameters can be chained together. For instance, a category page with 5 color options, 4 size ranges, and 3 sorting rules can easily generate hundreds of unique URL variations for the exact same underlying inventory.
# Example of Uncontrolled Parameter Chain
https://example.com/shoes/running/?color=blue&size=10&sort=price_asc&utm_campaign=fall
To prevent these dynamic paths from consuming crawler capacity, engineering teams must implement strict technical remediation protocols, ensuring that parameter spaces are isolated from search bot discovery.
E-Commerce URL Patterns & Faceted Control
In e-commerce environments, faceted navigation (filters for size, color, brand, and price) is the primary driver of dynamic URLs. Without strict architectural boundaries, a single category hub can generate millions of thin, redundant URLs.
The Indexation Rule for Facets: Never allow search engines to index low-value, multi-select utility filters (e.g.,
/shoes/?color=red&size=10).Static Subcategory Conversion: For high-demand attribute combinations that possess proven organic search volume (e.g., “Men’s Red Running Shoes”), convert dynamic parameters into clean, static subfolder paths:
Unoptimized Dynamic:
https://example.com/shoes/?category=running&color=redOptimized Static:
https://example.com/shoes/running/red/
Remediation Protocol: Isolate utility sorting and filtering parameters using server-level
robots.txtdisallows, canonical tags pointing back to the master category hub, or client-side AJAX filtering.
Enterprise Site URL Patterns
For massive programmatic directories, job boards, real estate portals, or enterprise SaaS platforms with millions of database-driven pages, URL design must prioritize structural scalability and isolation.
Flat vs. Deep Hierarchical Trade-offs: Enterprise catalogs often choose between deep structures (
/real-estate/ny/new-york/luxury-condo) and flat structures (/properties/luxury-condo-ny). While deep structures offer explicit breadcrumb context, flat patterns are far more resilient to database restructuring and taxonomy shifts.Preventing Programmatic Thin Content: Programmatic SEO templates must enforce strict indexation gates. If a generated dynamic page does not meet a minimum inventory threshold (e.g., at least 5 unique items), the template must automatically inject a
noindex, followmeta tag or return a 404/410 status to prevent mass index bloat.
Multilingual & International URL Patterns
When scaling a domain across multiple geographic regions and languages, poorly configured URL structures frequently cause severe language-targeting confusion and international cannibalization.
The 3 Accepted International URL Patterns:
Subdirectories (
example.com/fr-fr/,example.com/en-us/): The recommended industry standard because they consolidate domain-wide authority into a single root property.Subdomains (
fr.example.com,us.example.com): Effective for isolating regional governance, but splits PageRank equity across separate host environments.ccTLDs (
example.fr,example.us): Strongest local user trust signals, but requires managing completely independent domain authorities and link-building profiles.
The Role of hreflang Annotations: Regardless of whether you use subdirectories or subdomains, every international URL must pair clean regional paths with bi-directional hreflang HTML link headers, explicitly informing Googlebot which regional variant to serve to users based on their language and geographic location.
Technical Remediation & Future-Proofing Framework
Identifying structural URL issues and parameter leaks is only half the battle. Technical SEOs and engineering teams must implement rigorous auditing workflows and defensive engineering practices to clean up existing index bloat and ensure future scalability.
Diagnostic Step 1: Uncovering Parameter Leaks in Google Search Console
Before applying code-level fixes, you must quantify how search engines are interacting with your parameter space using Google Search Console (GSC):
Reviewing the Page Indexing Report: Navigate to GSC → Indexing → Pages. Look closely at exclusion categories like “Duplicate without user-selected canonical” or “Crawled – currently not indexed”. Accumulations here indicate that unmanaged parameter URLs are wasting bot resources.
Regex Performance Filtering: Go to GSC → Search Results → Pages, apply a custom regex filter (
\?.*=), and check if sorting or filtering query strings are capturing impressions while splitting traffic away from core category hubs.
Diagnostic Step 2: Simulating Crawl Paths via Screaming Frog
To measure how deeply internal links expose parameter variations to crawlers:
Configure your crawler to follow query strings (Configuration → Spider → Crawl).
Run a full site audit and review the Parameters tab. Examine the Inlinks report for high-volume parameter URLs to identify sidebar navigation elements or dynamic filter grids leaking internal link equity.
Actionable Remediation Protocols: How to Fix & Prevent
Depending on the severity of your site’s parameter bloat, deploy one of three core technical controls:
1. The Canonical Trap Correction (When to use rel="canonical")
The Issue: Many developers assume placing a canonical tag on a parameter URL saves crawl budget. In reality, Googlebot must still execute an HTTP request and render the page HTML to read the canonical tag.
The Fix: Use canonical tags only when external links or internal user clicks require consolidating PageRank back to a master category URL (e.g., pointing
/shoes/?color=redto/shoes/). For heavy utility parameters, rely on robots.txt disallows instead.
2. Engine-Level Disallow Rules (robots.txt)
The Fix: For massive, non-indexable utility parameters that threaten your daily crawl budget, block crawler access at the server level:
# Block sorting, filtering, and session tracking parameters
User-agent: Googlebot
Disallow: /*?*sort=
Disallow: /*?*filter=
Disallow: /*?*sessionid=
3. The Enterprise Solution: AJAX, PushState & PRG Pattern
To permanently prevent parameter crawlers from choking your server, decouple user-facing filter UI from crawler-accessible HTML links using the Post-Redirect-Get (PRG) pattern and client-side JavaScript (history.pushState):
User Interaction: When a user clicks a filter (e.g., sort by price), JavaScript updates the UI dynamically via AJAX.
URL State Update:
history.pushStateupdates the browser URL bar for user bookmarking without exposing raw parameterhreflinks in the DOM.Isolated Crawlers: Search engine bots crawling the raw HTML encounter clean static category links, completely shielded from combinatorial parameter traps.
The Golden Rules of URL Changes & Migrations
Altering an established, ranking URL path is one of the highest-risk operations in technical SEO. A URL accumulates authority signals, historical user engagement, and backlink PageRank equity over time. Modifying that string breaks those connections unless a strict migration protocol is executed.
The Permanent Asset Principle
Treat URLs as permanent digital assets. Modifying a URL simply for cosmetic preference or minor aesthetic organization creates unnecessary risk:
Temporary Volatility: Even with flawless 301 redirects, search engines require time to re-crawl, re-index, and transfer authority signals to the new URL destination.
Crawl Capacity Burden: Large-scale URL changes force search crawlers to re-evaluate millions of paths simultaneously, temporarily throttling the discovery of new site content.
Step-by-Step Execution Protocol for URL Migration
When a URL update is structurally unavoidable such as during a platform re-architecture or brand consolidation, execute this step-by-step technical workflow:
Establish 1:1 Mapping Rules
Create a strict 1:1 redirection map connecting every historical URL directly to its exact structural equivalent on the new path. Never mass-redirect legacy product or category URLs to the homepage.
Deploy Server-Level 301 Redirects
Implement permanent 301 redirects at the edge or server level (Nginx, Apache, or CDN edge workers). Ensure redirects respond immediately without chaining through multiple hop URLs (Old URL -> Intermediate URL -> New URL).
Update In-Domain Link Graphs
Never rely on 301 redirects to handle internal traffic long-term. Perform a site-wide database replace or code update to point all internal navigational, body, and footer links directly to the new canonical URL paths.
Refresh Sitemaps & Inspect Indexation
Remove old URLs from your primary XML sitemap and append the new URL paths. Submit the updated sitemap in Google Search Console and monitor the Page Indexing report for status updates and redirect errors.
Troubleshooting Common Migration Issues
To ensure your team handles unexpected ranking shifts or crawler issues quickly, refer to this diagnostic checklist:
| Issue / Symptom | Root Cause | Technical Resolution |
| Redirect Chain | The old URL redirects through multiple intermediary URLs before reaching the destination. | Update server rules to route directly from the legacy URL to the final destination in a single HTTP 301 hop. |
| Soft 404 Flag | The redirected destination page content does not match the search intent of the original path. | Align page content on the target URL with the legacy page intent, or return an explicit 410 Gone status. |
| Loss of PageRank | Internal links continue to point to old URLs, forcing crawlers to parse redirect hops. | Audit the site using Screaming Frog and batch-update database references to point directly to the new URL paths. |
Is Changing a URL Truly Necessary?
During website redesigns or content updates, webmasters frequently make a critical mistake: assuming that if a page’s content gets upgraded or the URL looks outdated, the URL string should be changed to match. This mindset can throw your entire website into severe ranking volatility.
A URL serves purely as a page’s Permanent Digital Address. Unless you face extreme circumstances (such as a complete site re-architecture, a massive site-wide migration, or persistent unfixable 404s), never modify an already live and ranking URL path.
Changing an Existing URL Will Not Boost Your Rankings: Many SEOs fall into the trap of changing a live URL just to insert keywords or make it ‘cleaner.’ Google’s search advocates have repeatedly confirmed that modifying an established URL for keyword placement provides zero ranking boost and unnecessarily risks losing established link equity during the redirect re-indexing phase.
Do Not Fear Content-URL Mismatches: If a page originally launched with a basic URL slug and later expanded into an exhaustive master guide, changing the URL path is still unnecessary.
Real-World Case Study (
ahmadfrazseo.com):On my own domain, I have a live guide with the URL slug
/what-is-technical-seo/. It originally launched as a simple introductory post. Later, I expanded it into a Technical SEO Master Guide. However, I deliberately chose not to change the URL slug. Why? Because that slug was the official address that had accumulated internal link equity, bookmarks, and high-value external backlinks. Changing the URL would have unnecessarily fractured that established equity flow.
Actionable Protocol: When to Change vs. When to Keep
Perform an Analytical Audit First: If a URL change feels unavoidable, audit the path using Ahrefs or Semrush before taking action. Evaluate the volume of internal equity and external backlinks flowing into that specific path. Always look at the broader picture—if the legacy URL works, leave it untouched!
Reserve Changes for Extreme Circumstances Only: Unless the page intent completely changes from scratch or the database structure collapses, keep the existing URL. If a URL update is structurally forced, deploy strict 301 redirects—but never make a habit of repeatedly changing URLs.
The Future-Proofing Rule: Moving forward, plan URL slugs thoroughly before publishing new pages. Select broad, evergreen, and descriptive slugs so that when content evolves over time, your URL infrastructure never becomes a bottleneck.
Frequently Asked Questions (SEO-Friendly URLs)
What is URL structure?
A URL structure is the specific, standardized formatting and architectural hierarchy used to define the address of a web page on the internet. It communicates the exact directory path, folder context, and page identifier to web browsers and search engine crawlers, mapping how individual pages fit within a site’s overall Information Architecture (IA).
What is an SEO-friendly URL structure?
An SEO-friendly URL structure is a clean, human-readable, and crawler-efficient web address optimized to pass maximum semantic context to search engines while providing a trustworthy, clear snippet for users. Key characteristics include:
Using descriptive, keyword-focused slugs separated by hyphens (
-).Enforcing strict lowercase characters and secure
https://protocols.Maintaining shallow directory depth (reachable within 1–3 clicks).
Isolating dynamic parameters (
?sort=,?color=) to prevent crawl budget waste and duplicate content traps.
What is the general structure of a URL?
The general structure of a standard web URL consists of five key technical components:
Protocol (
https://): The secure transport communication layer.Host / Domain Name (
example.comorsub.example.com): The primary domain identity and authority hub.Port (
:443or:80): The server network port (usually implicit and omitted in web browsers).Path & Slug (
/category/page-slug/): The hierarchical directory location and resource slug identifying the specific page.Query String / Parameters (
?sort=price_asc): Dynamic key-value pairs used for server-side state filtering, analytics, or session tracking.
Is URL structure a direct Google ranking factor?
Google considers URL strings a very lightweight relevance signal, primarily used for initial page discovery. However, simply adding keywords to a URL will not improve rankings. The real SEO value of a well-designed URL structure is technical: preventing crawl bloat, ensuring proper indexation hierarchy, and improving user trust in search snippets.
Should I include dates or categories in my URL slug?
For evergreen content and standard landing pages, avoid dates in your URL slugs. Appending dates (e.g., /2024/10/seo-guide/) creates long-term architectural debt—when you update the content in future years, the URL makes it appear outdated in search snippets, forcing unnecessary 301 redirects to remove the date.
Regarding categories: include a category folder (/technical-seo/url-structure/) only if your site architecture relies on strict physical taxonomies. For e-commerce catalogs or large blogs prone to re-categorization, adopt flat product/post slugs (/url-structure-guide/) to keep URLs resilient against site reorganizations.
Are hyphens (-) really better than underscores (_) in URLs?
Yes, absolutely. Search engine parsers follow strict character rules:
Hyphens (
-): Treated as explicit word separators. A slug like/url-structureis parsed as two distinct entity tokens:urlandstructure.Underscores (
_): Treated as word joiners. A slug like/url_structureis parsed as a single concatenated token (url_structure).
Google officially recommends using hyphens exclusively across all web addresses and URL parameters.
What is the ideal character length for an SEO-friendly URL?
While web standards support URLs up to 2,000+ characters, search engines and human users heavily favor concise paths. Industry study data shows that top-ranking SERP URLs average around 50 to 60 characters. Aim to keep your URL path short, descriptive, and focused purely on your primary target keyword while removing unnecessary stop words (a, an, the, of, in).
Static URLs vs. Dynamic Parameter URLs: Which is better?
Static URLs are always superior for primary indexable content. Static paths (e.g., /running-shoes/) are easy for crawlers to parse, simple for users to share, and immune to canonical confusion. Dynamic parameter URLs (e.g., ?category=shoes&sort=price) should be reserved strictly for utility state changes like sorting or temporary user filtering, and must be isolated using robots.txt disallows, canonical tags, or client-side AJAX execution to prevent crawler traps.
If I upgrade my content, should I change the URL to match?
No. Never change an already live, ranking, and indexable URL simply for cosmetic alignment or minor content upgrades. Live URLs act as permanent digital addresses that accumulate historical link juice, internal authority, and backlink equity over time. Changing a live URL introduces ranking volatility and forces search crawlers to re-evaluate the path. Only execute URL changes during critical site migrations, and always enforce strict 1:1 server-level 301 redirects.
Conclusion
An SEO-friendly URL structure is the foundational spine of enterprise website architecture—balancing clean topical context for search engines with high-trust legibility for human users. By maintaining shallow folder depth, enforcing standardized slug hygiene, isolating dynamic parameters, and treating live URLs as permanent digital assets, technical teams can permanently eliminate crawl waste and protect domain-wide organic equity as the site scales.
Need Help Audit-Proofing Your Site Architecture?
Building a scalable, crawler-efficient URL hierarchy for enterprise catalogs or complex CMS migrations requires precision engineering. If you are planning a site redesign, struggling with parameter bloat, or need an audit of your site’s technical architecture: