
Imagine publishing dozens of high-value product pages or well-researched blog posts, only to watch them sit indefinitely in Google Search Console under “Discovered – currently not indexed”. You audit your on-page elements, check your internal links, and verify your XML sitemap, everything looks immaculate. Yet, search engines refuse to index your revenue-generating content.
In enterprise technical SEO, the culprit behind this invisible wall is frequently a crawl trap.
Crawl traps occur when bad dynamic routing, unchecked URL parameters, or recursive link generation force search engine bots like Googlebot into an infinite loop. Instead of crawling your core site architecture, crawlers waste host CPU cycles and daily bandwidth processing thousands of duplicate, thin, or auto-generated URLs.
Left unchecked, a single recursive parameter can multiply a 10,000-page e-commerce site into an unmanageable 2-million-page crawler maze. Slowing down server response times and freezing indexation across your entire domain.
In This Guide, You Will Learn:
The Root Architecture Flaws: How booking calendars, recursive relative paths, session tokens, and multi-facet filters trigger infinite loops.
Why Traditional Directives Fail: Why
rel="canonical"and<meta name="robots" content="noindex">tags cannot stop active crawl waste.Diagnostic Forensics: How to uncover hidden loops using Google Search Console, Screaming Frog tree visualizers, and raw server access logs.
Engineering-Level Fixes: Step-by-step code implementations for Nginx/Apache rewrites,
robots.txtwildcard rules, and framework guardrails across Shopify, WooCommerce, and Next.js.
What Is a Crawl Trap And Why Does It Paralyze Googlebot?
A crawl trap is a structural or algorithmic web architecture flaw that generates an infinite stream of unique, recursive URLs.
When a search engine spider like Googlebot hits a crawl trap, it encounters a never-ending chain of links that dynamically mutate with every fetch request. Because search engine crawlers are programmed to discover new content by following internal links, they get stuck executing thousands of automated HTTP GET requests across virtually identical, programmatically generated pages.
The Hidden Cost: Crawl Limit Depletion & Indexation Stalls
Search engines assign every domain a finite crawl capacity limit based on server responsiveness and host authority. When Googlebot gets stuck in a recursive URL loop, three severe technical problems occur:
Crawl Allowance Waste: Instead of discovering new blog posts, evaluating updated product inventory, or processing schema updates, Googlebot spends its daily host request budget fetching thousands of empty calendar months or dynamic parameter combinations.
Indexing Delay for Revenue Pages: High-value landing pages sit in Google’s render queue for days or weeks because the crawler’s allocated time on your server was completely consumed by the trap.
Server Overhead & Response Degradation: Massive bot traffic spikes caused by uncontrolled crawler loops can overwhelm application servers, triggering elevated 5xx HTTP response codes and slowing down TTFB (Time to First Byte) for real human visitors.
Now that we understand how infinite HTTP GET request loops deplete your daily crawl allowance and freeze core indexation, let’s examine the five most common architecture flaws that trigger these traps in live production environments.
5 Common Architecture Flaws That Create Infinite Crawler Traps
Crawl traps are rarely created intentionally; they are almost always the side effect of modern dynamic routing, misconfigured CMS modules, or unhandled edge cases in web code.
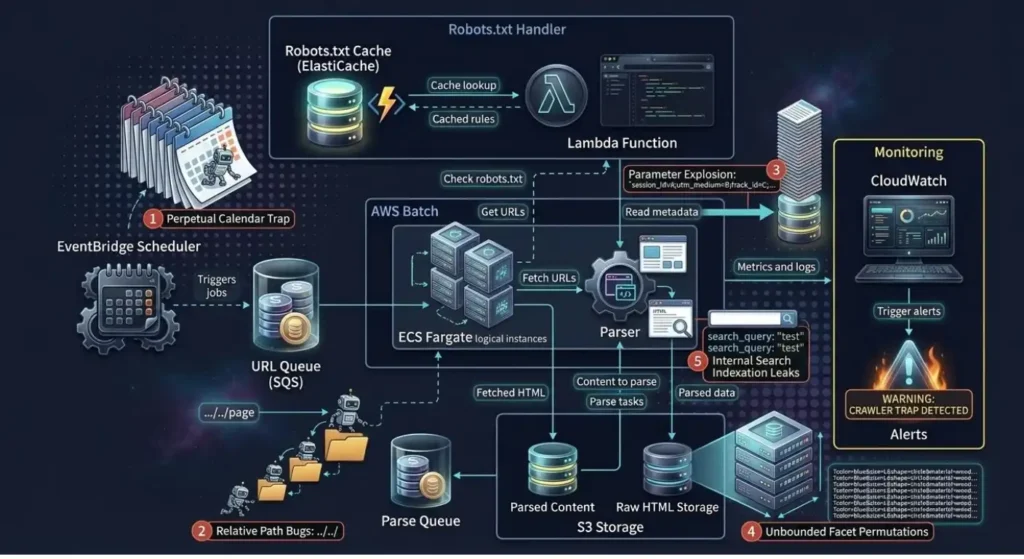
1. The Infinite Calendar & Event Trap
Dynamic booking widgets and event calendars often include “Next Month” and “Previous Month” navigation links that dynamically build new dates into the URL string without an end boundary:
https://example.com/events/2026/10/
https://example.com/events/2026/11/
...
https://example.com/events/2099/12/
Because calendar scripts continuously generate valid 200 OK responses with empty event listings, search bots will follow these pagination controls endlessly into future and past decades, treating every empty month as a new document.
2. Relative Path URL Generation Bugs
When an HTML document omits a explicit <base> tag or uses incorrect relative link syntax inside a CMS template, relative links can resolve recursively against the current directory path:
<!-- Base page: https://example.com/products/shoes/ -->
<a href="shoes/running">Running Shoes</a>

<!-- Renders as: https://example.com/products/shoes/shoes/running -->
<!-- Then: https://example.com/products/shoes/shoes/shoes/running -->
As search spiders traverse these recursive paths, the web server continuously processes the malformed routing strings—creating hundreds of thousands of valid, duplicate page variations for a single product category.
3. Session ID & Tracking Parameter Explosions
Legacy application frameworks or custom middleware sometimes attach unique session identifiers (e.g., PHPSESSID=8a9b0c...) or dynamic analytics parameters directly to internal navigation links rather than storing them in cookies or local storage.
Every time a search crawler visits the site, the server issues a new session ID. This causes search engines to discover duplicate versions of every single page on the site for every unique bot request, exploding the URL graph exponentially.
4. Unbounded Facet Permutations
While controlled faceted navigation is essential for e-commerce stores, allowing users and crawlers to select multi-attribute combinations without strict controls creates massive combinatorial bloat:
30 Colors × 15 Sizes × 10 Brands × 5 Price Ranges = 22,500 URL Variations per Category
Without parameter handling rules, dynamic filter combinations generate millions of low-value, duplicate page states that swallow Googlebot’s processing budget.
5. Internal Search & Auto-Complete Indexation Leaks
Exposing site search result pages to crawlers through unmasked search input forms, dynamic auto-complete links, or raw XML sitemaps creates an open door for automated parameter traps.
Spam bots or web scrapers targeting your site search box can generate millions of artificial search queries (e.g., /search?q=xyz), forcing Googlebot to fetch and index infinitely generated thin search result pages.
Identifying how these five architecture flaws form is only half the battle; the real risk lies in relying on indexing directives that fail to stop crawlers at the network layer.
Why Canonical Tags and Meta Noindex Won't Save You From a Crawl Trap
A common and dangerous misconception in technical SEO is assuming that adding a rel="canonical" tag or a <meta name="robots" content="noindex"> directive will neutralize an active crawl trap.
While these directives manage indexation, they completely fail to prevent crawl waste.
THE HTTP FETCH REQUIREMENT DILEMMA
- Googlebot discovers a dynamic, infinite parameter URL.
- To read the <meta name=”robots” content=”noindex”> or rel=”canonical” tag… Googlebot MUST first execute a complete HTTP GET request to download the DOM.
- Result: Your server spends bandwidth and CPU rendering pages that won’t be indexed.
The HTTP Fetch Requirement
Search engine bots do not know a page contains a noindex tag or points its canonical elsewhere until they perform an HTTP GET request, download the document payload, and parse the HTML response header or <head> tags.
If your site generates 500,000 infinite calendar or relative path URLs:
Canonical Tags: Googlebot will still execute 500,000 HTTP fetches to read the canonical target.
Noindex Directives: Googlebot will still consume 500,000 server execution cycles before discarding the pages from the index.
In both scenarios, your host’s daily crawl allowance is fully spent on processing the trap, leaving actual revenue-generating URLs stranded in the rendering pipeline.
Directives Hierarchy for Infinite Loops
To permanently eliminate a crawl trap, you must prevent the HTTP fetch from ever occurring or terminate the connection instantly at the edge server level.
| Technical Directive | Stops Crawl Waste? | Prevents Indexation? | Primary Use Case for Crawl Traps |
| Robots.txt Disallow | YES | YES (Over time) | Primary defense to block parameter patterns before HTTP request execution. |
| HTTP 410 / 404 Status | NO (Initial fetch) | YES | Drops trap URLs out of the crawl queue permanently after initial discovery. |
| Server Rewrite / 301 | NO (Triggers redirect) | YES | Resolves recursive path bugs back to valid, clean root URLs. |
| Meta Noindex | NO | YES | Invalid for traps. Forces continuous bot fetching. |
| Rel=”Canonical” | NO | YES | Invalid for traps. Fails to reduce server request volume. |
Now that we’ve established why indexation directives fall short, let’s look at the exact diagnostic workflows you can use in Google Search Console, Screaming Frog, and raw server logs to detect infinite loops before they crash your server.
How to Audit and Identify Crawl Traps Before They Damage Search Rankings?
Detecting a crawl trap early requires monitoring data across three independent layers: indexation diagnostics in Search Console, controlled spider simulations, and real-time server log file analysis.
1. Catching Exponential Parameter Bloat in Google Search Console
Search Console provides the earliest macro-level signal that Googlebot has encountered an infinite URL loop.
Page Indexing Report Spikes: Navigate to Indexing ➔ Pages and check the “Discovered – currently not indexed” and “Crawled – currently not indexed” reports. A sudden, sharp vertical upward trend (e.g., jumping from 10,000 to 500,000 excluded URLs) almost always signals an active crawl trap.
Isolating Loop Patterns via Regex Filters: Use the Search Console URL search filter with custom regular expressions to isolate repeating dynamic path strings:
# Matches recursive folder paths (e.g., /shoes/shoes/ or /category/category/)
\/([a-zA-Z0-9-]+)\/\1\/

# Matches dynamic calendar years beyond 2030
\/events\/20[3-9][0-9]\/
2. Tracing Infinite Loops Using Screaming Frog
Standard website crawlers will get stuck in infinite loops just like Googlebot unless you configure safety bounds or explicitly analyze directory depth.
Setting Max Crawl Depth Controls: Before launching an enterprise audit, go to Configuration ➔ Spider ➔ Limits and cap Max Crawl Depth to
10or15. This prevents the crawler from hanging indefinitely while capturing the exact path where the trap originates.Directory Tree Visualizer: After running the audit, navigate to Visualisations ➔ Directory Tree Graph. A crawl trap will display as an abnormally long, linear branch extending far beyond your standard architecture depth (e.g., Depth 12+ displaying repeated directory names).
3. Log File Forensics: Pinpointing Bot Traffic Spikes
Server access logs provide definitive, real-time proof of Googlebot getting trapped in a loop.
To parse raw Nginx or Apache access logs directly via terminal, execute grep and awk commands to aggregate request frequencies by User-Agent and query patterns:
# Count total requests by Googlebot targeting parameter or date strings
grep "Googlebot" /var/log/nginx/access.log | awk '{print $7}' | grep -E "\?|/20[3-9][0-9]/" | sort | uniq -c | sort -nr | head -n 20
If the log output reveals Googlebot making thousands of requests per hour to single-parameter variations (e.g., ?sort=price&session=123...), you have confirmed an active, high-severity crawl trap consuming host bandwidth.
Once log forensics and crawler visualizers pinpoint the exact origin of an infinite loop, the next step is applying targeted engineering fixes to permanently block and neutralize the trap.
How to Fix and Neutralize Active Crawl Traps?
Fixing an active crawl trap requires immediate server-side intervention to halt incoming bot requests and clean up the structural code generating the bad URLs.
1. Stopping the Bleeding: Edge-Level Blocking via Robots.txt & Nginx Rules
When a crawl trap is actively consuming server resources, your immediate priority is terminating HTTP GET requests before they execute heavy application logic.
Robots.txt Wildcard Pattern Disallows
Use strict wildcard rules in robots.txt to instantly disallow search spiders from crawling dynamic parameter strings or recursive path structures:
User-agent: Googlebot
# Block calendar loops beyond specific years
Disallow: /events/203*/
Disallow: /events/204*/

# Block recursive path loops
Disallow: /*/shoes/shoes/

# Block dynamic session tokens and query strings
Disallow: /*PHPSESSID=*
Disallow: /*?*sort=*&sort=*
Server-Level Nginx / Apache Rule Blocks
For high-severity traps that bypass static directives, enforce a hard HTTP 410 Gone or HTTP 403 Forbidden response at the web server layer before the request reaches your CMS database or rendering engine:
# Nginx block for recursive relative URL loops
location ~* ^/.*(shoes|clothing)/(shoes|clothing)/ {
    return 410;
}

# Nginx block for unchecked calendar traps
location ~* ^/events/20[3-9][0-9]/ {
    return 410;
}
Returning a hard 410 Gone response instructs Googlebot that the resource has been permanently removed, forcing the crawler to drop the URL from its active queue faster than standard 404 Not Found statuses.
2. Eliminating the Root Architectural Flaws
Temporary blocking rules buy you time, but permanent resolution requires rewriting the underlying application code.
PERMANENT ARCHITECTURAL REMEDIATION
- Calendar Widgets: Enforce hard date limits (e.g., max 12 months in advance).
- Relative Path Bugs: Explicitly declare <base href=”https://example.com/”> in <head>.
- Session Parameters: Migrate PHPSESSID strings into HTTP-only secure cookies.
- Search Indexing: Apply <meta name=”robots” content=”noindex, follow”> on /search.
Fixing Calendar Traps
Client-Side Navigation: Render future and past calendar navigation via JavaScript AJAX calls or client-side UI states without exposing static
<a href>links for invalid date ranges.Hard Date Limits: Hardcode dynamic routing boundary conditions in your backend controller (e.g., throwing a
404or410status if a requested date is more than 12 months in the future).
Fixing Relative Path Loops
Ensure every HTML document includes a fully qualified <base> tag in the <head> section to force relative links to resolve against the root domain rather than the current URI directory:
<!-- Explicitly set base URL to prevent recursive path concatenation -->
<head>
  <base href="https://example.com/" />
</head>
Fixing Session ID & Search Leak Traps
Cookie-Based Sessions: Configure your application server (PHP, Node, Django) to store session state strictly in client cookies rather than appending URI parameters.
Internal Search Handling: Block internal search pages (
/search?q=) inrobots.txtand add a<meta name="robots" content="noindex, follow">tag to prevent external search engines from indexing thin internal search queries.
How to Handle Crawl Traps During a Technical SEO Audit
When auditing a medium-to-large e-commerce or publishing site, crawl traps rarely announce themselves cleanly. They hide deep within site architecture or manifest only under specific bot request conditions.
To systematically identify and eliminate them during an audit, follow this 4-step diagnostic protocol:
Step 1: Benchmark Crawl Depth & URL Ratios (Screaming Frog / Lumar).
Step 2: Cross-Reference Google Search Console Exclusions vs. Log Spikes.
Step 3: Test Multi-User-Agent Rendering & Head Responses.
Step 4: Isolate Pattern Regex & Deploy Edge Disallows or 410 Responses.
Step 1: Run Capped Spiders to Detect Infinite URL Expansion
Launch a site crawl using Screaming Frog or Lumar, but enforce a strict Max Crawl Depth limit of 15.
If the crawler hits the depth limit while discovering millions of URLs on a site that should only have 20,000 pages, sort the crawl list by URL Length or Folder Depth.
Look for repeating path segments (e.g.,
/category/subcategory/subcategory/) or endless query parameters.
Step 2: Correlate GSC Exclusions with Server Log Requests
Compare the Discovered – currently not indexed report in Search Console against raw server log files:
If Search Console shows 500,000 excluded URLs matching a specific parameter pattern (e.g.,
?dir=asc&order=price), cross-check your Nginx/Apache logs to see if Googlebot is making continuous HTTP GET requests to those URLs daily.
Step 3: Test Custom User-Agent Rendering
Some legacy CMS platforms or middleware render dynamic links differently for search engine bots than for human browsers.
Use
curlor Postman to fetch target pages using the officialGooglebotUser-Agent string:
curl -A "Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)" -I "https://example.com/target-page"
Inspect the raw HTML DOM payload to verify whether session IDs, relative paths, or dynamic calendar links are being generated exclusively for crawlers.
Step 4: Apply Immediate Edge Mitigation & Permanent CMS Patching
Once the trap pattern is verified, issue an immediate emergency block in robots.txt using wildcards to halt host resource depletion. Assign a backend developer ticket to patch the underlying CMS routing logic.
Now that we got clear ideas how to fix and handle crawl traps during SEO audit. Let’s understand how to prevent specific framework architecture from it.
Step-by-Step Prevention Across Shopify, WooCommerce & Next.js
Different tech stacks trigger crawl traps through unique platform mechanics. Here is how to lock down routing and parameter structures across the three most common web setups.
1. Shopify: Securing App-Generated Parameters & Collection Loops
Shopify’s default architecture natively uses vendor, tag, and filter parameters that third-party apps frequently expose to search engines.
Editing
robots.txt.liquid: Customize your Shopify theme’srobots.txt.liquidfile to block dynamic collection filters and app-generated sorting strings:
{% for rule in group.rules %}
  {{ rule.directive }}: {{ rule.value }}
{% endfor %}

# Block Shopify filter and tag parameters
Disallow: /*?*filter.v.price*
Disallow: /*?*filter.v.option*
Disallow: /collections/*+*
Disallow: /collections/*/*?*sort_by=*
Fixing Vendor & Tag Links: Liquid templates frequently output
<a href="/collections/all/vendor-name">or tagged collection links inside filtering drawers. Update theme code to render dynamic filters using data attributes or JavaScript UI triggers rather than crawlable<a href>links.
2. WooCommerce / WordPress: Disabling Dynamic Archive & Widget Traps
WordPress sites often suffer from calendar widgets, multi-layered widget filters, and dynamic search query loops.
Eliminate Calendar Widgets: Remove native WordPress calendar widgets (
WP_Widget_Calendar) from sidebars and footers. These widgets dynamically link to historical month archives, inviting crawlers into endless historical archives.Server-Level Nginx Rules for WooCommerce: Add custom Nginx location blocks to strip multi-filter query strings before WordPress executes PHP queries:
# Block unchecked WooCommerce attribute combinations
if ($query_string ~* "filter_[a-z0-9_-]+=.+&filter_[a-z0-9_-]+=.+") {
    return 410;
}
3. Headless / Next.js: Catch-All Route Guardrails ([...slug])
In modern React and Next.js App Router applications, developers frequently use dynamic catch-all routes (app/[...slug]/page.tsx) to handle flexible CMS rendering. Without strict validation, arbitrary URI path extensions return 200 OK status codes instead of 404 Not Found.
// app/[...slug]/page.tsx
import { notFound } from 'next/navigation';
import { validateSlugPath } from '@/lib/cms';

interface PageProps {
  params: { slug: string[] };
}

export default async function DynamicPage({ params }: PageProps) {
  // Validate if the requested route array matches a real CMS document
  const pageData = await validateSlugPath(params.slug);

  // CRITICAL: If path doesn't exist or exceeds valid depth, throw a hard 404
  if (!pageData || params.slug.length > 4) {
    notFound();
  }

  return <main>{/* Render Page Content */}</main>;
}
By enforcing strict depth checks (params.slug.length > 4) and triggering notFound() when CMS queries return null, you prevent Next.js from rendering soft-200 pages on infinite dynamic paths.
With platform-specific guardrails configured to block structural leaks, let’s address the most common edge-case questions developers and SEO teams ask when diagnosing infinite crawler loops.
Frequently Asked Questions About Crawl Traps
What is the primary difference between a crawl trap and a standard 404 error?
A 404 error occurs when a crawler requests a non-existent URL and receives an immediate HTTP 404 Not Found response header. The request terminates instantly.
A crawl trap, by contrast, dynamically generates valid HTTP 200 OK or HTTP 302 Redirect responses for an infinite series of newly calculated URLs. Instead of stopping, the crawler follows internal links into an endless loop, continuously consuming host bandwidth.
Can adding rel="nofollow" to internal links eliminate a crawl trap?
No. While rel="nofollow" signals that search engines shouldn’t transfer PageRank across a link, Googlebot can still discover and crawl those target URLs through other paths, XML sitemaps, or external backlinks. Relying on nofollow to block dynamic parameter traps is ineffective; edge-level robots.txt disallows or server-level 410 Gone status codes are required.
Do crawl traps leak PageRank or internal link equity?
Yes. In site architecture network graphs, infinite crawl traps act as sink nodes. When hundreds of thousands of internal links point to infinite calendar months, filter combinations, or session IDs, internal link equity (PageRank) flows into non-indexable, low-value pages rather than consolidating onto your core revenue and category pages.
Can a massive crawl trap crash an e-commerce server?
Yes. If multiple search engine spiders (Googlebot, Bingbot, Yandex, AhrefsBot) enter an unchecked multi-facet or relative path loop simultaneously, they can generate hundreds of concurrent requests per second. On database-heavy platforms like WooCommerce or Magento, executing uncached PHP/SQL queries for every dynamic URL variant can spike CPU utilization to 100%, triggering server-wide 503 Service Unavailable errors for real users.
Key Takeaways
Eliminating crawl traps is a core requirement for preserving host crawl budget, ensuring rapid indexation for revenue pages, and maintaining a clean site architecture.
Prevent Fetch Execution: Indexing directives like
rel="canonical"and<meta name="robots" content="noindex">fail to stop crawl waste because Googlebot must fetch the document to read them.Block at the Edge: Use strict
robots.txtwildcard disallows or server-level Nginx410 Gonerules to terminate recursive request loops instantly at the network boundary.Maintain Dynamic Route Guardrails: Enforce boundary controls on booking calendars, sanitize relative link generation, and apply catch-all validation rules (
notFound()) in modern JavaScript frameworks like Next.js.
Is Parameter Bloat or Crawl Waste Stalling Your Search Performance?
Need Help Neutralizing Technical Crawl Budget Waste?
If your e-commerce platform or enterprise website is experiencing indexation delays, exponential parameter bloat, or crawler performance bottlenecks, a technical audit can isolate and resolve the root architectural issues.
[Explore Technical SEO Services] [Explore SEO Audit Services] OR [Book an Enterprise SEO Strategy Consultation]
Explore Other Articles Under Technical SEO Side
Pillar Blogs
What is Technical SEO? (Parent Blog)
- Crawlability and Indexability in SEO (Child Blog)