When a visitor clicks a link on your website and hits a blank “404 Page Not Found” screen, the immediate damage is clear: the user gets frustrated and leaves.
What is less obvious is what happens behind the scenes.
Every broken link on your domain acts as a dead-end for search engine crawlers. It halts the flow of internal link equity, wastes rendering bandwidth, and leaves valuable backlink authority trapped in dead pages.
While Google won’t issue a direct manual penalty just because a few URLs return a 404 status code, leaving broken links unmanaged quietly erodes your site’s crawl efficiency and overall search authority.
In this guide, we will break down the true technical cost of broken links, differentiate between Hard 404s, 410s, and Soft 404s, and establish a step-by-step diagnostic workflow to clean your architecture without creating redirect chains or wasting PageRank.
What Are Broken Links (and How Do They Actually Happen?)
A broken link is simply any hyperlink that points to a resource: a web page, an image, or a downloadable document, that no longer exists or cannot be reached by the server.
When a browser or search engine bot requests that resource, the server responds with an HTTP status code indicating a failure (most commonly a 404 Not Found or 500 Server Error).
To diagnose and fix them efficiently, you must first categorize broken links into three distinct structural types:
- Internal Broken Links: Links originating on your site pointing to missing pages on your own domain. These directly interrupt crawler paths and break your internal PageRank distribution.
- External Outbound Broken Links: Links on your site pointing to dead pages on third-party websites. These ruin citation trust and tell Google your content is unmaintained.
- Inbound Broken Backlinks (Inbound 404s): External websites linking to URLs on your domain that no longer exist. These represent pure equity leakage, external authority pointing straight into a wall.
The Root Causes Behind 404 Spikes
Broken links rarely happen out of nowhere. They are almost always the side effect of uncoordinated site updates:
- URL Structural Changes Without Redirects: Renaming a URL slug or changing a parent category folder without mapping a permanent redirect.
- Deleting Outdated Content: Removing old blog posts, expired promotional pages, or out-of-stock products without evaluating incoming internal or external links.
- Manual Linking Typos: Simple human errors when adding inline contextual links inside articles (e.g., typing .co instead of .com or misspelling a slug).
- Domain Migrations: Shifting from HTTP to HTTPS, or migrating to a new domain without a 1:1 redirect map.
Understanding how links break is straightforward, but to prioritize fixes during a technical audit, you need to see exactly what happens to your site’s authority when Googlebot hits a dead end.
How Broken Links Impact Technical SEO & Site Health
A common misconception in technical SEO is that Google penalizes domains simply for having 404 errors.
Google’s official stance has always been clear: 404 errors are a normal part of the web. Pages get deleted, products go out of stock, and content expires.
However, when broken links accumulate across your internal architecture, they trigger three severe structural problems that directly impair your search performance.
1. Link Equity Leakage (Trapped PageRank)
Internal link equity (PageRank) flows through your website like a network of pipes. Every internal link passes authority from high-power pages (like your homepage or core service hubs) down to deeper supporting pages.
When an internal link points to a 404 page, that authority pathway instantly terminates. The PageRank flowing into that link vanishes into a dead end instead of being redistributed to other live, indexable pages.
The issue is even worse with Inbound 404s. If an authoritative external publication links to a page on your site that now returns a 404, all that hard-won backlink equity is completely wasted until you reclaim it.
2. Crawl Budget & Rendering Waste
Googlebot operates on allocated crawl resources. On smaller sites, this is rarely an issue, but on enterprise domains or sites with deep architectures, crawling broken URLs creates major friction.
Every time Googlebot requests a broken URL, follows a link to a dead page, or gets caught parsing unhandled error loops, it spends bandwidth fetching useless HTTP response codes.
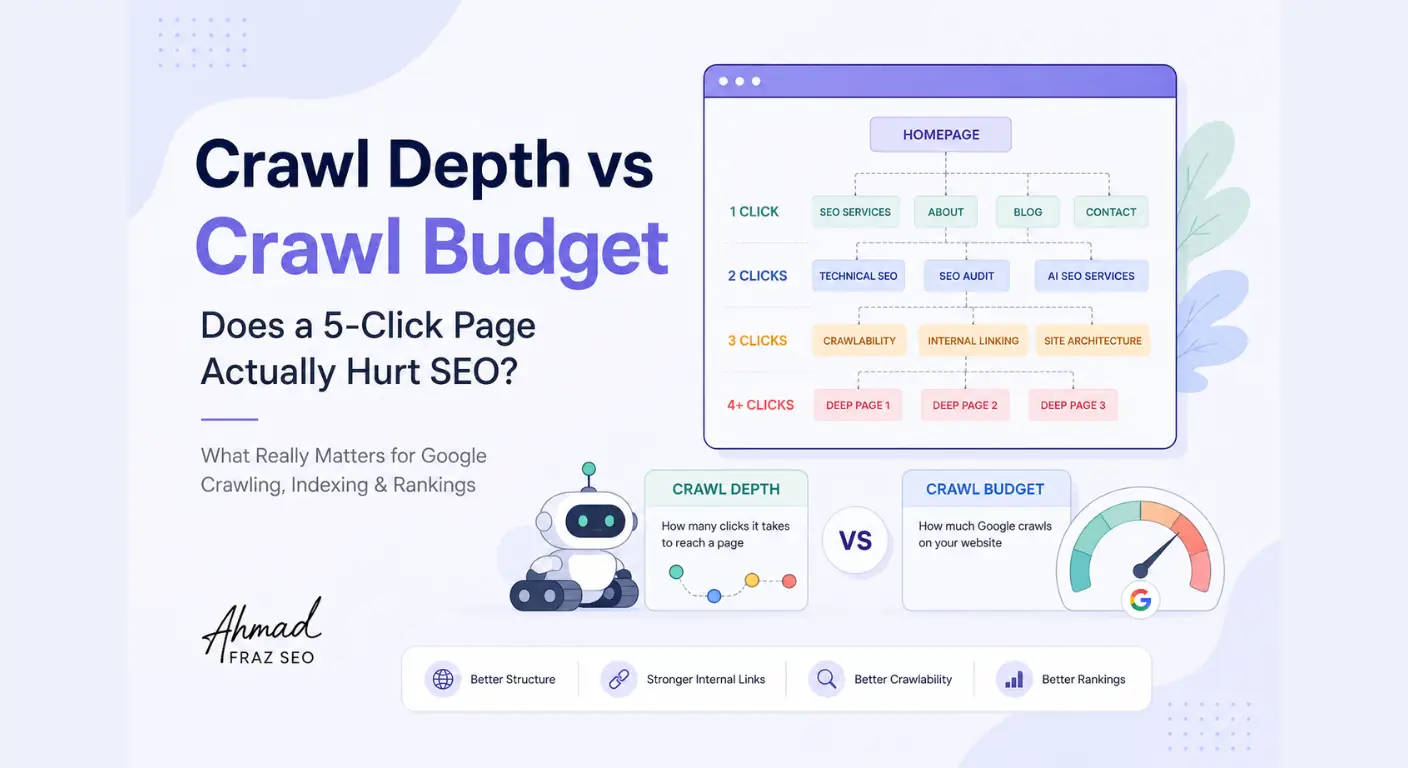
Instead of discovering new content or re-crawling updated revenue pages, bot resources are consumed by dead paths. If your site structure forces crawlers to navigate multiple levels down just to hit dead ends, you severely compound your overall crawl friction.
3. User Engagement & Quality Signals
When visitors hit a 404 page, their immediate reaction is to hit the back button and return to the search engine results page (SERP), a behavior known as pogo-sticking.
While pogo-sticking itself isn’t a direct algorithmic penalty, consistent user drops, broken conversion paths, and short session durations signal to search algorithms that your domain is unmaintained or failing to satisfy user intent.
To stop equity leakage and crawl waste effectively, you must first understand that not all “Not Found” errors are handled the same way by search engine crawlers. Let’s look at the critical differences between Hard and Soft 404s.
HTTP Status Codes Dissected: Hard 404 vs 410 Gone vs Soft 404
When cleaning up dead URLs, many webmasters treat all missing pages the same way. However, search engines evaluate HTTP response codes differently depending on the signal your server sends back.
Choosing the wrong status code can lead to delayed index removal, wasted rendering budget, or accidental indexing of empty pages.
1. Hard 404 (Not Found)
A Hard 404 is the standard server response indicating that the requested URL does not exist on the server.
- Googlebot Behavior: When Googlebot encounters a 404, it stops processing the page and queues the URL for de-indexing. However, Google does not drop the page immediately; it re-crawls the URL several times over a few weeks to verify if the missing state is temporary or permanent.
- Best Used For: Pages deleted without a direct replacement, accidental URL removals, or routine content expiry where no similar resource exists.
2. 410 Gone (Permanently Removed)
A 410 response explicitly tells the search engine crawler: “This page was deleted intentionally and will never return.”
- Googlebot Behavior: Unlike a 404, a 410 status code acts as an accelerated removal request. Googlebot drops a 410 page from its index significantly faster because it skips the multi-stage re-verification process.
- Best Used For: High-volume content pruning, mass deletion of spam URLs from a hacked directory, or permanently retired service/product pages that you want purged from search results immediately.
3. The Soft 404 Trap (The Silent Crawl & Rendering Killer)
A Soft 404 occurs when your server returns a 200 OK success status code, but the page content clearly signals to a user or search engine that the resource is missing (e.g., displaying a “Sorry, product not found” message, an empty category grid, or a page with almost no text).
- Googlebot & Rendering Impact: Because your server returns a 200 OK, Googlebot treats the page as valid and sends it to the rendering pipeline. The Web Rendering Service (WRS) executes JavaScript and parses HTML layout before algorithms detect that the page contains no real content. This burns massive rendering and crawl budget.
- The Penalty Effect: Once Google flags a URL as a Soft 404, it ignores internal links originating from it and strips away any passed link equity, meaning mass-redirecting irrelevant dead pages to your homepage will almost always be re-classified as Soft 404s.
Technical Comparison for Search Engine Crawlers & AI Search Bots
Search engine crawlers, LLM training bots, and AI Overviews process these server states differently during indexing and retrieval phases:
Status Code / State | Server Header Sent | Googlebot Indexing Speed | Rendering & Crawl Impact | Link Equity Handling | AI Overview / Search Bot Treatment |
Hard 404 (Not Found) | 404 Not Found | Moderate (de-indexes after verification window) | Low (crawled, but rendering skipped) | Dropped (Equity lost if not redirected) | Ignored; excluded from entity knowledge graphs. |
410 Gone | 410 Gone | Fast (immediate queue for index removal) | Minimal (fastest path to stop bot fetches) | Dropped (Equity lost permanently) | Excluded immediately; prevents outdated citation hallucinations. |
Soft 404 | 200 OK | Delayed (flagged as thin/empty post-rendering) | High (burns WRS rendering & DOM execution) | Nullified (Google rejects passed equity) | High risk; can cause AI bots to synthesize empty or misleading snippets. |
Now that you know how search bots evaluate different status codes, the next step is running a diagnostic audit to uncover every broken link before they impact your site architecture.
How to Find and Check Broken Links (Step-by-Step Identification)
Locating every broken link across a domain requires distinguishing between on-page link detection (quick inline checks) and full-site architectural crawling (deep diagnostic checks).
Depending on the scale of your site and your role, here are the most effective ways to find and check broken links step-by-step.
How to Check Broken Links on a Website: Step-by-Step
Step 1: Run an Automated Site Crawler (Best Method for Full Audits)
For an accurate, enterprise-level audit, use a crawling spider like Screaming Frog, Sitebulb, or Ahrefs Site Audit.
- Launch your crawler, enter your domain name, and hit Start.
- Once the crawl reaches 100%, navigate to the Response Codes or Issues report.
- Filter the URLs by HTTP status code 4xx Client Error.
- Click on any individual broken URL and inspect its Inlinks or Source Page panel to see the exact page and anchor text where the dead link is placed.
Step 2: Inspect Google Search Console for Discovered 404s
To see which broken links Googlebot has actually stumbled upon while crawling your domain:
- Log into Google Search Console and select your property.
- Go to Indexing → Pages in the left sidebar.
- Scroll down to the “Why pages aren’t indexed” section and click Not Found (404).
- Review the list of URLs. Click on any URL to see example referring pages that Googlebot followed to discover that dead link.
Step 3: Spot-Check Single Pages via Browser Extensions
If you are performing content updates or reviewing a single landing page before publishing, full-site crawls are unnecessary.
- Use browser extensions like Check My Links or Redirect Path (Chrome).
- Open the target page, trigger the extension, and it will automatically highlight valid links in green and broken/404 links in red directly on the rendered DOM.
When you search for or check broken backlinks, you’ll find many third-party tools available, such as Screaming Frog, Sitebulb, Ahrefs, and others. The best approach is to first go to the Pages section in Google Search Console and check there.
However, before we continue with the article, let’s take a quick look at a comparison table of some of the top broken-link-checking tools currently available in the market, including Google Search Console, and see how they compare with each other.
Then we’ll come back to our blog, because the purpose of this article is not to provide a list of broken-link-checking tools. The purpose is to make you aware of how to find broken links and, more importantly, how to fix them.
Top Broken Link Checker Tools (Tabular Comparison)
Tool Type | Primary Examples | Best Used For | Key Advantage |
Desktop Crawlers | Screaming Frog, Sitebulb | Deep technical audits & JS-rendered sites | Locates exact line-by-line internal link sources (Inlinks). |
Cloud SEO Suites | Ahrefs, SEMrush, Moz | Inbound broken backlink reclamation & scheduling | Finds external sites linking to dead pages on your domain. |
Free Search Tools | Google Search Console | Verifying Googlebot-discovered errors | Shows live crawl friction directly from Google’s index. |
Browser Extensions | Check My Links, Link Checker | Quick single-page content reviews | Real-time visual feedback while editing content in your CMS. |
Once you have a list of internal 404s, GSC errors, and broken backlinks, you need a decision framework to fix each URL.
How to Fix Broken Links? - Remember these 4 Rules
The biggest mistake webmasters make after running an audit is applying a single blanket fix, usually mass-redirecting every broken URL to the homepage.
Handling broken links effectively requires a diagnostic decision process based on relevance, link equity, and user intent.
Rule 1: The 1:1 Relevant 301 Redirect (Preserving Authority)
Use a permanent 301 Redirect when a page has moved to a new URL, or when a deleted page has an equivalent, highly relevant replacement.
- When to apply: A product version was updated (e.g., /product-v1/ to /product-v2/), a slug was renamed, or a deleted blog post has a direct successor covering the exact same topic.
- Technical requirement: The target URL must satisfy the original search intent. If you redirect a broken page about “Technical SEO Audits” to a page about “Social Media Marketing,” search engine algorithms will ignore the redirect and classify it as a Soft 404, stripping away passed link equity.
Rule 2: Updating or Removing Internal Links at the Source
If an internal link on your site is broken, creating a 301 redirect is only a secondary patch, not the primary fix.
- Why? Pointing an internal link to a URL that redirects to another URL introduces latency and creates an unnecessary hop for crawlers.
- The Best Practice: Edit the source page inside your CMS directly. Change the href attribute to point straight to the live target page (200 OK). If the deleted page has no replacement, remove the hyperlink tag altogether while preserving the surrounding editorial text.
Rule 3: Intentional Removal with 410 Gone
Not every deleted page needs to live on through a redirect. If content was pruned intentionally and has no logical replacement, letting it return a 404 Not Found or 410 Gone status code is the correct technical choice.
- When to apply: Outdated promotional campaigns, thin low-traffic pages deleted during content pruning, or obsolete product lines.
- Why it works: Returning a 410 Gone explicitly signals to Googlebot that the removal was deliberate, allowing search engines to purge the URL from the index faster and stop allocating crawl resources to it.
Rule 4: Link Reclamation (Recovering Inbound 404 Equity)
When external publications link to a broken URL on your domain, you cannot edit their source code directly. You have two options to reclaim that lost authority:
- Targeted 301 Redirect: Implement a 1:1 redirect from the dead backlink URL to your closest parent category or relevant article.
- Outreach for High-Value Backlinks: If the backlink comes from a premier industry publication (e.g., Forbes, Wikipedia, or a top media site), send a polite outreach email to the editor or author noting that the resource moved, and provide the new, updated URL.
Even with a clear decision framework, it is easy to make implementation mistakes that introduce new technical issues into your site architecture.
Do You Need to Fix All Broken Links? Let's Undertstand this Technical Point
When webmasters run a site audit for the first time, seeing hundreds of 404 errors in tools often causes immediate panic. The natural instinct is to try and “clean the dashboard” by setting up mass redirects for every single reported broken URL.
However, in advanced technical SEO, a 404 status code is not always a bug. Sometimes it is the correct, intended technical behavior.
Attempting to fix or redirect system-generated, non-content 404s can actually pollute your site architecture, create soft 404 loops, and waste crawl budget on non-existent endpoints.
The Anatomy of “Ignorable” 404s (Auto-Generated & System Noise)
In CMS platforms like WordPress, web applications, and custom frameworks, crawlers often uncover paths that were never actual web pages meant for human readers or search engine indexing.
Here are the primary categories of broken links where doing nothing is the absolute best SEO decision:
1. Uninstalled Plugin Assets & Theme Artifacts
When you delete or update a plugin or theme, its underlying CSS, JavaScript files, image assets, or directory folders disappear. External scrapers or cached internal references might still try to request them.
Examples:
https://example.com/wp-content/plugins/old-plugin-name/assets/script.jshttps://example.com/wp-content/themes/hello-elementor/inc/deprecated-file.phphttps://example.com/wp-content/uploads/2023/04/deleted-temp-banner.png
Why leave them as 404: These are asset files, not content URLs. Redirecting a missing
.jsor.cssfile to a live HTML page makes zero technical sense to search engine bots and will be flagged as a Soft 404.
2. REST API Endpoints & Framework Hooks
Modern themes and plugins utilize REST APIs and JSON endpoints to pass data dynamically. Audit crawlers often try to follow these raw API paths as if they were standard hyperlinks.
Example:
https://example.com/wp-json/elementskit/v1/widget-datahttps://example.com/wp-json/wp/v2/posts/9999
Why leave them as 404: API endpoints return raw data or authentication errors when accessed directly via a browser. They are not indexable content pages. Returning a 404/403 status code when the endpoint is unneeded protects server security and stops search bots from trying to index API output.
3. Malicious Vulnerability Probes & Bot Scans
Every public website on the internet is continuously probed by automated security bots looking for known vulnerabilities in outdated software (e.g., /wp-login.php, /admin.php, .env, /backup.sql).
Examples:
https://example.com/wp-config.php.bakhttps://example.com/v2/_async/https://example.com/phpmyadmin/
Why leave them as 404: You want these paths to return a hard 404 (or 403 Forbidden). Never redirect security probe paths to your homepage, as it masks security attempts and tricks crawlers into indexing junk administrative parameter URLs.
4. Outdated Feed URLs, Trackbacks, & Parameter Junk
Older CMS setups automatically generated RSS feeds, trackback URLs, or tag filter combinations that no longer exist or were disabled.
Examples:
https://example.com/blog-post/feed/https://example.com/category/tech/trackback/https://example.com/?replytocom=123
Why leave them as 404: Feeding dead parameter variations or duplicate RSS feeds to search bots wastes rendering resources. Letting them return 404 allows Googlebot to clean its historical discovery queue naturally.
Why Google Handles Auto-Generated 404s Automatically
Search engines are sophisticated enough to understand the lifecycle of web resources. When Googlebot stumbles upon an auto-generated or missing asset 404:
Verification Phase: Googlebot logs the
404 Not Foundresponse header.Exponential Backoff: It re-crawls the dead URL a few times over subsequent weeks with decreasing frequency.
Queue Purging: Once Googlebot confirms the path remains dead and holds no internal links from live HTML pages, it silently drops the URL from its active crawling queue.
The Quick Filter: When Should You ACTUALLY Care About a 404?
Before spending time fixing a 404 error, run it through this quick 3-point diagnostic test:
| Question | If YES | If NO |
| 1. Is it a live HTML page with user search intent? | FIX IT: 301 redirect to relevant page or restore content. | Move to Question 2. |
| 2. Does it have valuable external backlinks (Inbound 404)? | FIX IT: 301 redirect to reclaim link equity. | Move to Question 3. |
| 3. Is it linked internally inside your live navigation/content? | FIX IT: Remove or update the link in your CMS. | IGNORE IT: Let it return a natural 404. |
Key Takeaway: A clean SEO audit isn’t about achieving a “Zero 404 Errors” score in third-party software. It’s about ensuring that indexable content and page equity flow freely, while system noise and dead assets fade away naturally.
Common Mistakes: What NOT to Do When Fixing Broken Links
Fixing broken links without understanding crawler mechanics can cause more damage to your site architecture than the original 404 errors.
Avoid these four common technical traps during cleanup:
1. The “Redirect Everything to Homepage” Mistake
When faced with hundreds of 404 warnings in audit tools, many site owners set up a blanket rule redirecting every dead URL straight to https://example.com/
- Why it fails: Google evaluates redirects based on topical relevance. A homepage covers your brand’s core offering. It does not satisfy the search intent of a deep, specific article or product page.
- The Result: Search engines treat irrelevant homepage redirects as Soft 404s. Google ignores the redirect, strips away any incoming link equity, and still flags the page as an error in Search Console.
2. Creating Redirect Loops and Chains
A Redirect Chain occurs when an old broken link points to a URL that redirects to another URL (301 → 301 → 200 OK). A Redirect Loop happens when URL A redirects to URL B, which points back to URL A (301 ↔ 301).
- Why it fails: Each hop in a redirect chain adds server latency, slows down page load speed, and consumes additional crawl budget.
- The Result: Search engine crawlers eventually abort following chains if they exceed 3 to 5 hops, dropping both the page request and the passed link equity. Always ensure internal links point directly to the final destination URL (200 OK).
3. Blocking 404 Pages in robots.txt
Disallowing a path containing broken URLs in your robots.txt file might make audit tool warnings disappear, but it introduces a major indexing conflict.
- Why it fails: robots.txt instructs search engine bots not to crawl a directory. If Googlebot is blocked from fetching the URL, it cannot see the 404 Not Found or 410 Gone HTTP response code returned by the server.
- The Result: The dead URL remains stuck in Google’s index indefinitely, and any external backlink authority pointing to that path remains completely trapped. Allow crawlers to fetch dead pages so they can process the status code naturally.
4. Mass-Redirecting Missing Plugin, Theme, or Asset 404s
Fixing every error code in audit tools blindly often leads to redirecting internal WordPress plugin files, theme assets (/wp-content/themes/…), or REST API endpoints (/wp-json/…).
When a plugin is uninstalled or updated, its associated CSS/JS files disappear. Creating 301 redirects for missing system assets confuses search bots, creates useless redirect overhead, and pollutes your .htaccess or server configuration. Allow system, theme, and API 404s to fail naturally. Googlebot understands asset lifecycle removals and will drop them without affecting your organic rankings.
Frequently Asked Questions (FAQs)
1. Do broken links directly drop your Google rankings?
Google does not issue a direct algorithmic penalty for having 404 errors, as missing pages are a normal part of the web. However, unmanaged broken links indirectly hurt rankings by trapping internal link equity (PageRank), burning crawl budget, and increasing bounce rates when users hit dead ends.
2. Is it necessary to address or fix every single 404 broken link?
No, it is not necessary (or recommended) to fix every single 404 error reported in audit tools or Google Search Console, especially when dealing with internal system files, plugin assets, or API endpoints.
3. How often should I check my website for broken links?
For small to medium websites (under 1,000 pages), running a full-site broken link check once a month is sufficient. For large ecommerce sites, enterprise publications, or sites undergoing frequent content updates, run automated weekly crawls or set up continuous monitoring via cloud SEO platforms.
4. Should I redirect all 404 errors to my homepage?
No. Redirecting irrelevant broken URLs to your homepage is a bad technical SEO practice. Search engine algorithms evaluate redirect relevance, and if the destination page does not match the search intent of the original URL, Google will classify the redirect as a Soft 404 and reject the passed link equity anyway.
5. What is the difference between a 404 Not Found and a 410 Gone status code?
A 404 Not Found tells search engines that a page is missing, prompting Googlebot to re-crawl the URL several times to confirm it is permanently dead. A 410 Gone explicitly states that the page was intentionally deleted and will never return, forcing search engines to purge the URL from the index much faster.
6. Why does Screaming Frog show broken links that Google Search Console misses?
Screaming Frog crawls your raw site code line-by-line, identifying every broken link present in your HTML or JavaScript. Google Search Console only reports 404 errors for URLs that Googlebot has actually attempted to fetch during its crawl passes. If Googlebot hasn’t crawled a deep page recently, GSC will not display the broken link.
7. How do I fix a broken link coming from an external website (Inbound 404)?
Since you cannot edit the code on a third-party domain, fix inbound broken links by setting up a 1:1 permanent 301 Redirect from the dead URL to the most relevant live page on your domain. If the backlink comes from a high-authority publication, you can also reach out to the author to update the URL directly.
Conclusion
Managing broken links in SEO is not a one-time emergency task. It is an essential technical maintenance routine.
By systematically auditing your architecture, understanding the technical differences between status codes, and reserving 301 redirects for topical matches, you protect your site from crawl waste, preserve valuable backlink equity, and provide a seamless navigation path for both search engines and users.
Need Help Auditing Your Site's Architecture?
Cleaning up broken links, redirect chains, and crawl bottlenecks can get tricky, especially on large domains or during site migrations. If you want a technical SEO audit to protect your crawl budget and reclaim lost backlink equity, you may reach out to me. And if you want to explore what Technical SEO services I offer, you are always welcome to explore. Let’s clean up your site’s foundation together.