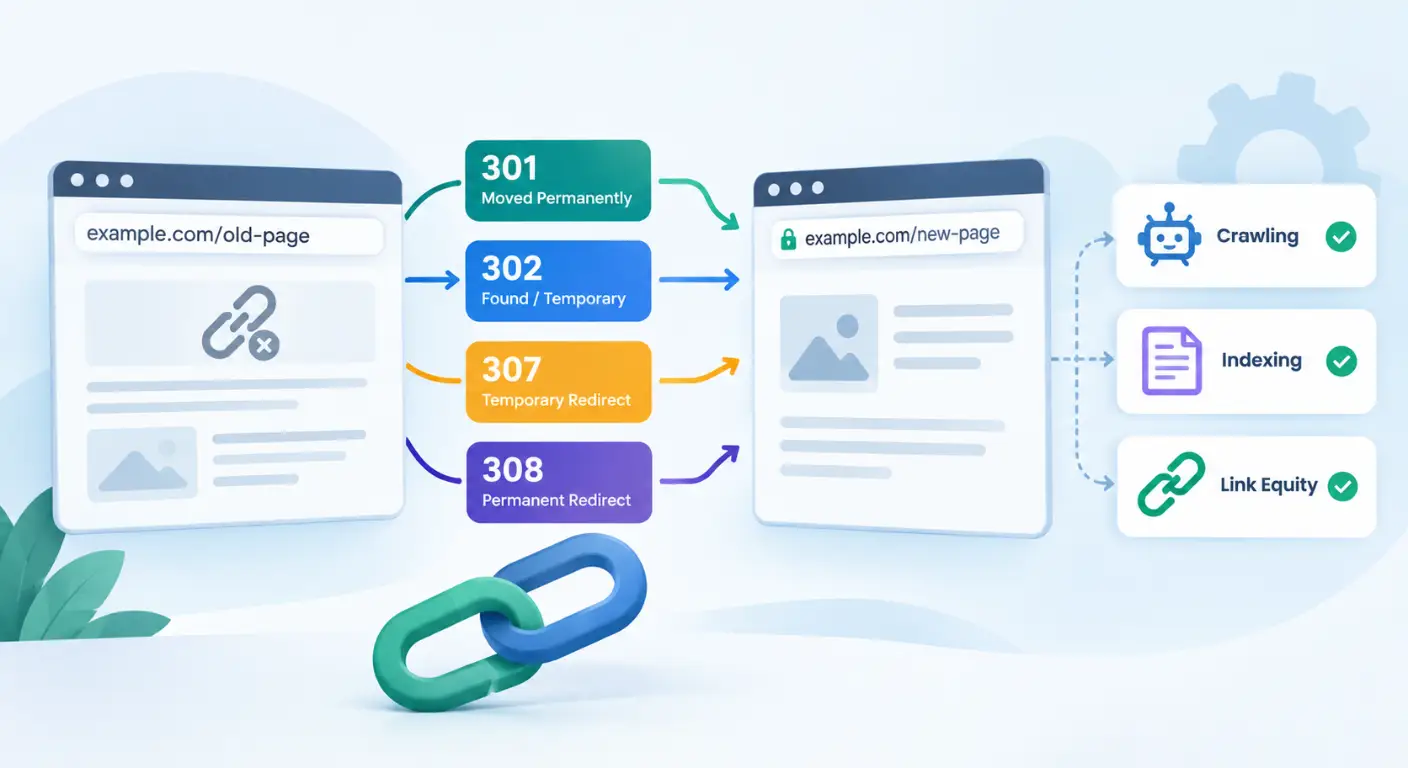
Changing a URL on your website sounds like a simple task until you have to decide what happens to the old one.
Should it redirect permanently or temporarily? What is the actual difference between a 301 and a 302? What happens to the hard-earned backlinks and organic rankings attached to that old URL? And what if you redirect a page to something completely unrelated?
For non-technical site owners and marketing managers, these decisions often feel like hidden developer configurations. But for search engine bots, a redirect is a explicit directive. It tells crawlers where to send user traffic, how to pass ranking authority (link equity or PageRank), and whether to update their search index.
If implemented correctly, redirects preserve your site’s visibility during updates. If handled poorly, they create broken user paths, trap link equity, waste server resources, and trigger indexation drops.
In this guide, we will break down the mechanics of SEO redirects, moving from the basics of HTTP status codes to advanced diagnostic workflows. So you can manage URL changes without losing organic performance.
What Are SEO Redirects? (And Why Do They Matter?)
An SEO redirect is an automatic instruction that sends both website visitors and search engine bots from one requested URL (the source) to a different URL (the destination).
For example, if a user or search bot requests: https://example.com/old-page/
The server immediately routes them to: https://example.com/new-page/
[User / Search Bot Request] ──> [Old URL: /old-page/]
│
(HTTP 301/302)
▼
[New URL: /new-page/] ──> [200 OK Content Served]
Common Reasons You Need Redirects
In day-to-day website management, you typically use redirects when:
A URL structure changes: Renaming a blog post slug or updating product categories.
Consolidating overlapping pages: Merging multiple thin articles into one comprehensive master guide.
Protocol upgrades: Forcing all insecure
HTTPrequests to secureHTTPSURLs.Domain rebranding: Moving your entire site from an old domain name to a new brand domain.
Deleting outdated content: Pointing a deleted product page to its updated direct replacement.
For search engines, the central question isn’t just whether a page redirects, but how it redirects, what status code it sends, and whether the destination page matches the original search intent.
Before picking a status code number, it is crucial to understand where and how the server actually handles that redirection request.
The Mechanics of SEO Redirects: Server-Side vs Client-Side Executions
Not all redirects execute at the same layer of your web infrastructure. Depending on whether the instruction comes from the server header or the browser DOM (Document Object Model – the rendered page code), search engine crawlers process the redirect very differently.
Major types of SEO Redirects
1. Server-Side Redirects (The Gold Standard for Technical SEO)
Server-side redirects happen on the web server (such as Apache or Nginx) before any page content or HTML code is delivered to the browser.
When a crawler requests a URL, the server instantly sends back an HTTP response header (a background server message) with a 3xx status code and the new destination URL.
Why it’s best for SEO: Googlebot reads the HTTP header instantly without having to download, parse, or execute heavy page code. It saves crawl budget (the allocated limit of pages a bot crawls) and transfers link equity smoothly.
Primary Types:
301 Moved Permanently,302 Found (Temporary),307 Temporary Redirect, and308 Permanent Redirect.
2. Client-Side Redirects (Meta Refresh & JavaScript)
Client-side redirects trigger inside the browser after the initial server connection has already delivered raw HTML or JavaScript code.
Meta Refresh Redirects: An HTML tag placed in the
<head>section of a document that instructs the browser to reload another page after a set number of seconds (e.g.,<meta http-equiv="refresh" content="0;url=[https://example.com/new-page/](https://example.com/new-page/)">).JavaScript Redirects: Script code executed in the browser that sets
window.location.hrefto a new URL.
The SEO Risk of Client-Side Redirects:
Because Googlebot must pass client-side code through its Web Rendering Service (WRS – Google’s internal system that runs JavaScript like a real browser), processing client-side redirects takes significantly more time and computing power.
If rendering is delayed, Google may delay index updates, temporarily drop the page, or fail to pass full backlink authority. Always default to server-side HTTP redirects whenever possible.
Now that you know where redirects execute, let’s break down the specific HTTP status code numbers so you send the exact right signal to search crawlers.
HTTP Status Codes Breakdown: Crawl and Indexing Signals
Choosing the right HTTP status code is not about memorizing numbers, it is about telling search engine crawlers exactly what happened to your URL and what they should do with its ranking authority (link equity).
Google classifies redirects into two main buckets: Permanent Redirects and Temporary Redirects.
1. Permanent Redirects (301 & 308)
Permanent redirects tell search engine bots: “This old URL is gone forever. Purge it from your index and transfer all ranking authority to the new URL.”
301 Moved Permanently
The standard, most widely used server redirect for SEO page moves.
How Googlebot handles it: Google drops the old URL from search results and passes 100% of the accumulated PageRank (backlink authority) to the new destination URL.
When to use it: Permanent URL structure changes, domain migrations, HTTP to HTTPS switches, or replacing deleted articles with new replacements.
308 Permanent Redirect
The modern technical equivalent of a 301, defined under HTTP/1.1 specifications.
The Key Distinction: A
308forces browsers and search crawlers to preserve the exact HTTP request method (e.g.,POSTdata staysPOST). In a301, some older browsers incorrectly change aPOSTrequest to aGETrequest.When to use it: Complex web applications, API endpoints, or modern server setups where data payloads must remain intact during a permanent move. For standard content pages, Google treats
301and308identically.
2. Temporary Redirects (302, 303 & 307)
Temporary redirects send a fundamentally different instruction to crawlers: “The source page is temporarily located somewhere else, but the original URL will return soon. Do not update your index.”
302 Found (Formerly Moved Temporarily)
The default temporary redirect used across most CMS platforms.
How Googlebot handles it: Because Google expects the original page to return, it keeps the old URL indexed in search results and does not immediately transfer backlink equity to the temporary destination.
The “Long-Term 302” Exception: If you leave a
302redirect active for months, Googlebot’s algorithms will eventually assume you made a setup error. It will automatically treat the302as a permanent301and update the index anyway.
307 Temporary Redirect
The strict HTTP/1.1 successor to 302.
The Technical Precision: Just like a
308, a307guarantees that the HTTP request method will not change during the redirect.When to use it: Short-term promotional landing pages, A/B testing URL split tests, or temporary maintenance windows where form submissions (
POSTdata) must pass through safely.
303 See Other
A specialized status code used primarily in web application forms (e.g., after a user submits payment details, the server redirects them to a “Thank You” receipt page via GET to prevent duplicate form submissions). It carries zero SEO ranking consolidation value.
Status Codes at a Glance (The Technical Decision Matrix)
| Status Code | Move Type | Request Method Preserved? | Google Indexing Signal | PageRank Transfer | Best Real-World Use Case |
301 | Permanent | No (May convert POST to GET) | Index New URL | 100% Transfer | Permanent page moves, site restructures, HTTPS. |
302 | Temporary | No | Keep Old URL | Retained on Old | A/B testing, seasonal stock, short promotions. |
307 | Temporary | Yes (Strict Preservation) | Keep Old URL | Retained on Old | Temporary web app forms or payment gateways. |
308 | Permanent | Yes (Strict Preservation) | Index New URL | 100% Transfer | Modern API redirects or enterprise server setups. |
Choosing the correct status code sends the right indexing signal, but configuring redirects incorrectly can severely degrade crawler efficiency and server performance.
Crawl Budget & Indexing Latency: How Redirects Cause Crawl Friction
Search engine crawlers allocate a finite amount of time and server requests to your website, a concept known as Crawl Budget.
While a single clean 301 redirect takes milliseconds to process, poorly structured redirect chains and circular loops create massive crawl friction, slowing down content discovery across your entire site.
[Clean Redirect (1 Hop)] : [Old URL] ──(301)──> [Final URL] –> (Fast Crawl, Zero Latency)
[Redirect Chain (3 Hops)] : [URL A] ──(301)──> [URL B] ──(301)──> [URL C] ──(301)──> [Final URL]
└──> (Wasted Crawl Budget & Server Latency)
1. Redirect Chains: The Hidden Latency Multiplier
A Redirect Chain occurs when a redirected URL points to another URL that is also redirected, requiring multiple server hops before reaching a live page (200 OK).
The Latency Problem: Every additional hop forces Googlebot to initiate a new HTTP request, wait for the server response, and parse headers. On mobile devices or slow servers, a 3-hop chain can add 1 to 2 full seconds of page latency (delay).
Google’s Hop Limit: Googlebot will follow up to 5 redirect hops in a single pass. If a chain exceeds 5 hops, Googlebot aborts the fetch request, flags the URL as a crawl error, and drops any link equity passing through that chain.
2. Redirect Loops: The Infinite Fetch Trap
A Redirect Loop happens when URL configurations accidentally point back to themselves or an earlier step in the chain, creating an infinite loop (e.g., URL A → URL B → URL A).
When a crawler or browser encounters a loop:
The server continuously bounces requests back and forth.
The browser eventually crashes with a
"Too Many Redirects"error.Googlebot immediately drops the page from its crawling queue and eventually purges the URL from search index results.
A Real-World Redirect Loop I Encountered
I’ve actually dealt with a redirect loop on my own website, and it showed me how quickly a seemingly small URL change can turn into an indexing problem.
One of my pages originally used this URL:
https://ahmadfrazseo.com/about/
I later changed the page to:
https://ahmadfrazseo.com/about-me/
The intention was straightforward: the old /about/ URL should permanently redirect to the new /about-me/ URL.
However, the redirect configuration was not implemented correctly.
Instead of ending at the final page, the redirect sequence effectively became:
/about-me → /about-me/ → /about-me → /about-me/ → …
In other words, the destination URL itself was caught in another redirect back to the same URL without the trailing slash.
The browser eventually reported a “too many redirects” error because it could not reach a final page.
More importantly, the page became inaccessible to search engines while the problem existed. I later noticed that the page had disappeared from Google’s index as well.
After investigating the redirect configuration, I found the problem: the final URL that was supposed to serve the actual page was itself redirecting back to the non-slash version. The redirect chain never reached a normal 200 OK page.
I removed the conflicting redirect and made sure the final URL:
https://ahmadfrazseo.com/about-me/
served the actual page instead of redirecting again. Once the issue was fixed, the page became accessible and was indexed again.
The lesson is simple:
A redirect should always have a clear final destination.
When implementing or changing redirects, don’t just check whether the first 301 exists. Follow the entire sequence and verify that the final URL actually returns the intended page.
For important URLs, you can also use Google Search Console’s URL Inspection tool to check how Google sees the URL after the redirect is fixed. Google recommends testing redirects during URL changes and migrations rather than assuming they are working correctly.
Beyond technical loops and chains, another critical mistake that causes Google to reject redirects is routing pages to destinations that lack topical relevance.
The Soft 404 Pitfall: Irrelevant Redirects vs Topical Relevance
When managing URL changes, many site owners assume that setting up a 301 redirect to any live page is always better than returning a 404 Not Found error. This assumption often leads to mass-redirecting hundreds of deleted, out-of-stock, or expired pages directly to the homepage or a generic category page.
From a technical SEO standpoint, this practice backfires.
Search engine algorithms evaluate redirects based on topical equivalence, whether the destination page satisfies the same search intent as the source URL.
How Google Identifies Soft 404 Traps
When Googlebot follows a redirect, its Natural Language Processing (NLP) models compare the page content, entity structures, and contextual relevance of both URLs:
Topical Match: If you redirect
/seo-audit-checklist/to/technical-seo-audit-guide/, Google recognizes strong topical alignment. The redirect is honored, and link equity passes smoothly.Topical Mismatch: If you redirect
/seo-audit-checklist/to/contact-us/or your homepage, Googlebot detects an intent mismatch.
Instead of treating it as a valid permanent move, Google re-classifies the redirect as a Soft 404. When a Soft 404 is triggered, Google drops the source page from its index and completely rejects the passed PageRank, neutralizing your redirect strategy.
To prevent Soft 404 classification and avoid wasting crawl resources, you must choose the right technical mechanism for each specific URL scenario.
Redirect vs Canonical vs 404/410: Which Should You Use?
Understanding when to redirect, when to canonicalize, and when to let a page return an explicit error code is a core skill in architectural site maintenance.
1. Permanent Redirect (301 / 308)
Mechanism: Physical routing. The user and crawler are automatically moved away from the requested URL to a new destination.
When to use: The original URL no longer needs to exist or be accessed by humans, and a direct 1:1 topical equivalent exists.
2. Canonical Tag (rel=”canonical”)
Mechanism: Indexing hint. Both URLs remain physically accessible to users, but search engines are instructed which single URL should represent the content in search results.
When to use: Parameterized URLs (e.g., sorting/filtering options on e-commerce product grids), syndicated content, or regional URL variations that must remain live for user navigation.
3. Hard 404 / 410 Gone
Mechanism: Explicit removal signal. The server informs crawlers that the resource is missing (
404) or intentionally purged forever (410).When to use: Discontinued products or pruned content with no logical replacement. Allowing a page to return a clean
404or410is technically superior to forcing an irrelevant homepage redirect.
Scenario Decision Matrix
| Real-World Scenario | Best Technical Action | Why This Choice Works |
| URL Slug Renamed | 301 Permanent Redirect | Direct replacement; transfers 100% link equity to the new slug. |
| Old Article Consolidated into Master Guide | 301 Permanent Redirect | The master guide satisfies the user intent of the older thin article. |
Sorting Filters on Product Pages (?sort=price) | rel="canonical" to main category | Keeps filters usable for shoppers while consolidating indexing signals. |
| Out-of-Stock Seasonal Product (Returning Next Year) | 200 OK (Keep page live with “Out of Stock” notification) or 302 Temporary | Preserves rankings and URL history until stock is replenished. |
| Permanently Retired Service (No Replacement) | 410 Gone or 404 Not Found | Explicit removal signal; prompts Googlebot to purge the URL faster. |
Once you’ve mapped out the correct technical actions across your URLs, you need a diagnostic procedure to audit your site for hidden redirect issues.
How to Audit and Trace Redirects (Diagnostic Workflow)
A comprehensive redirect audit requires moving beyond high-level dashboard summaries to inspect raw HTTP response headers directly at the server level.
Step 1: Run an Architectural Crawl Trace (Screaming Frog)
Launch Screaming Frog, enter your domain URL, and execute a full crawl.
Select the Response Codes tab and filter by Redirection (3xx).
Export the Redirect Chains report (
Reports → Redirects → Redirect Chains).Inspect the output for:
Chain Length: Flag any URL sequence requiring more than 1 hop.
Redirect Loops: Highlight circular redirects immediately for server removal.
Final Destination Status: Verify that every chain ends in a valid
200 OKstatus, rather than a404or500server error.
Step 2: Inspect Response Headers via Command-Line (cURL)
For precise server-level debugging, web extensions can sometimes hide intermediary hops due to browser caching. Using a terminal cURL request shows the exact, un-cached server response:
curl -I -L https://example.com/old-page/
-I: Requests response headers only (skips body rendering).-L: Instructs cURL to follow all redirect hops sequentially.
Inspect the output headers to confirm that the server sends an exact HTTP/1.1 301 Moved Permanently (or 308) status code followed immediately by a single HTTP/1.1 200 OK final destination header.
Implementation Snippets: Apache vs Nginx
When configuring server-side redirects, always apply rules directly inside core server configuration files rather than relying on heavy CMS plugins.
Apache Server (.htaccess File)
# 1:1 Permanent Page Redirect
Redirect 301 /old-service/ https://example.com/new-service/

# Global HTTP to HTTPS Permanent Redirect
RewriteEngine On
RewriteCond %{HTTPS} off
RewriteRule ^(.*)$ https://%{HTTP_HOST}/$1 [R=301,L]
Nginx Server (nginx.conf File)
# 1:1 Permanent Page Redirect
location = /old-service/ {
    return 301 https://example.com/new-service/;
}

# Global HTTP to HTTPS Permanent Redirect
server {
    listen 80;
    server_name example.com www.example.com;
    return 301 https://example.com$request_uri;
}
With diagnostic testing and server implementations covered, let’s address the most common edge-case technical questions regarding redirects.
FAQs About SEO Redirects
1. What is a 301 redirect in SEO?
A 301 redirect is a permanent server-side instruction that automatically sends visitors and search engine crawlers from an old URL to a new URL. In SEO, a 301 redirect signals to Google that a page has permanently moved, safely transferring accumulated backlinks, ranking authority (link equity), and indexing signals from the old URL to the new destination.
2. Does a 301 redirect affect SEO?
Yes, but positively when implemented correctly. A 301 redirect preserves your search visibility by consolidating PageRank and directing Googlebot to the updated page without returning a 404 error. However, it can negatively impact SEO if it creates redirect chains (multiple hops), circular loops, or routes users to an topically irrelevant page that triggers a Soft 404 error.
3. What is the main difference between a 301 and a 302 redirect for SEO?
The primary difference is permanence and ranking consolidation:
301 (Permanent): Tells search engines to drop the old URL from the index and pass 100% of the backlink authority to the new URL.
302 (Temporary): Tells search engines to keep the old URL in the search index and withhold passing link equity because the original page is expected to return soon.
4. How long should you keep a 301 redirect active?
Google officially recommends keeping 301 redirects active for at least 365 days (1 year). This timeframe ensures Googlebot crawls the old URL multiple times, confirms the permanent redirection, and fully consolidates indexing signals. For critical landing pages and high-authority backlinks, it is best practice to keep 301 redirects active indefinitely.
5. Why is my 301 redirect showing as a Soft 404 in Google Search Console?
A 301 redirect triggers a Soft 404 warning when Google determines that the destination page does not match the search intent or topical content of the original URL (for example, redirecting a specific deleted product page directly to your homepage). To resolve this, change the redirect target to a topically equivalent page or allow the deleted page to return a clean 404 or 410 status code.
6. Can redirect chains harm my site’s organic rankings?
Yes. Redirect chains add server latency, slow down page load speeds, and burn crawl budget. If a chain exceeds 5 hops, Googlebot will abort the crawl request, flagging the URL as an error and dropping any link equity being passed.
7. What is the difference between a 301 and a 308 redirect?
Both indicate a permanent URL move. The technical difference is that a 308 strictly preserves the original HTTP request method (e.g., keeping a POST form request as POST), whereas a 301 allows older browsers to incorrectly convert a POST request into a GET request.
9. Do 301 redirects lose PageRank (link equity)?
No. Google has officially confirmed that modern 301 and 308 permanent redirects do not cause a loss in PageRank. However, if you redirect a page to an irrelevant destination (causing a Soft 404), Google’s algorithms will reject the passed equity.
Final Thoughts
Managing SEO redirects is not a cosmetic site task. It is a fundamental requirement for maintaining crawl efficiency, protecting backlink equity, and guiding search engine indexing decisions.
By choosing server-side status codes strategically, keeping redirect chains short, enforcing topical relevance, and tracing server headers regularly, you preserve your organic search authority through every URL evolution.
Need Help Cleaning Up Your Site's Architecture & Redirects?
Resolving persistent redirect loops, fixing Soft 404 drops, and executing complex URL restructures without losing search visibility requires precise technical diagnostics.
Exploring Technical Optimization? Learn how we architect bulletproof crawl paths and protect link equity through our Technical SEO Services.
Uncovering Hidden Site Errors? If you suspect redirect chains or crawl friction are silently capping your rankings, explore our comprehensive Website SEO Audit to identify and resolve underlying structural issues.
Have a specific technical issue on your site? Reach out for a technical SEO consultation—let’s review your architecture and ensure your foundation is built for growth.
Explore Other Articles Under Technical SEO Side
Pillar Blogs
What is Technical SEO? (Parent Blog)
- Crawlability and Indexability in SEO (Child Blog)